


I think most of us already have more personal data than we know what to do with.
Financial data is the easiest example. We have bank exports, card statements, Google Sheets, budgeting apps, CSV files, and random transaction records sitting somewhere. The data exists. Sometimes it is even organized.
But most of the time, nothing useful happens after that.
Maybe you open the sheet once in a while. Maybe you sort by category. Maybe you look at the total and feel vaguely bad for a few minutes. Then you close it because turning that raw data into something you can actually understand feels like another project.
I have definitely done this.
That is why Gencay’s experiment caught my attention. The interesting part is not just that he built a financial dashboard. It is that he took a very normal problem, having expense data but no clear way to use it, and turned it into something visual, searchable, and conversational.
Today’s guest post is from Gencay, the creator of LearnAIWithMe, and this is his third contribution to AI Maker. You might want to check out his previous posts on building SEO-optimized content with Claude Cowork and hidden NotebookLM features most people don’t know about.
What I like about his work is simple: he builds real things, tests them, and shares the lessons from the process.
If you want to learn more about what he writes, check out three of his posts here:
In this post, he uses Claude Code sub-agents to build a financial dashboard from expense data. You can inspect your spending, see trends, compare categories, forecast what might happen next, and even chat with your own financial history.
But the bigger lesson is the way he built it.
Instead of pushing one long task through one crowded Claude session, he split the work across five agents. One handled the frontend. One handled the data layer. One handled the charts. One handled predictions. One handled the AI counselor.
That feels like an important shift. A lot of AI building is moving from “ask one assistant to make the thing” to “direct a small group of agents around a real task.”
This post is a practical example of that shift, using a problem many of us probably already have sitting in our files.
Here’s Gencay.
Hello 👋🏻
Most people build apps with Claude Code one step at a time.
One file, then the next.
One feature, then the next.
There is a faster way. Sub-agents.
Five Claude instances can work in parallel.
Each one owns a piece of the app.
They coordinate through a shared spec folder and finish in a fraction of the time.
I used this to build a five-page expense dashboard with React on the frontend.
Let me walk you through it.
What Are Sub-Agents in Claude Code?
A sub-agent is a separate Claude instance that runs inside your main session.
It has its own context window, its own system prompt, and its own tool access.
You give it a task. It works in isolation. It returns a summary.
Three things make sub-agents different from just opening another Claude Code window.
They preserve your main context. Test logs, file searches, error traces stay in the sub-agent’s context.
You can run them in parallel. Five sub-agents, five jobs, at the same time.
You can restrict their tools. A research agent gets read-only. A builder agent gets write access. A tester agent gets bash.
To activate one, you can let Claude pick automatically or define your own in .claude/agents/ as a markdown file with YAML frontmatter.
For this build, I defined five.
What We’re Building
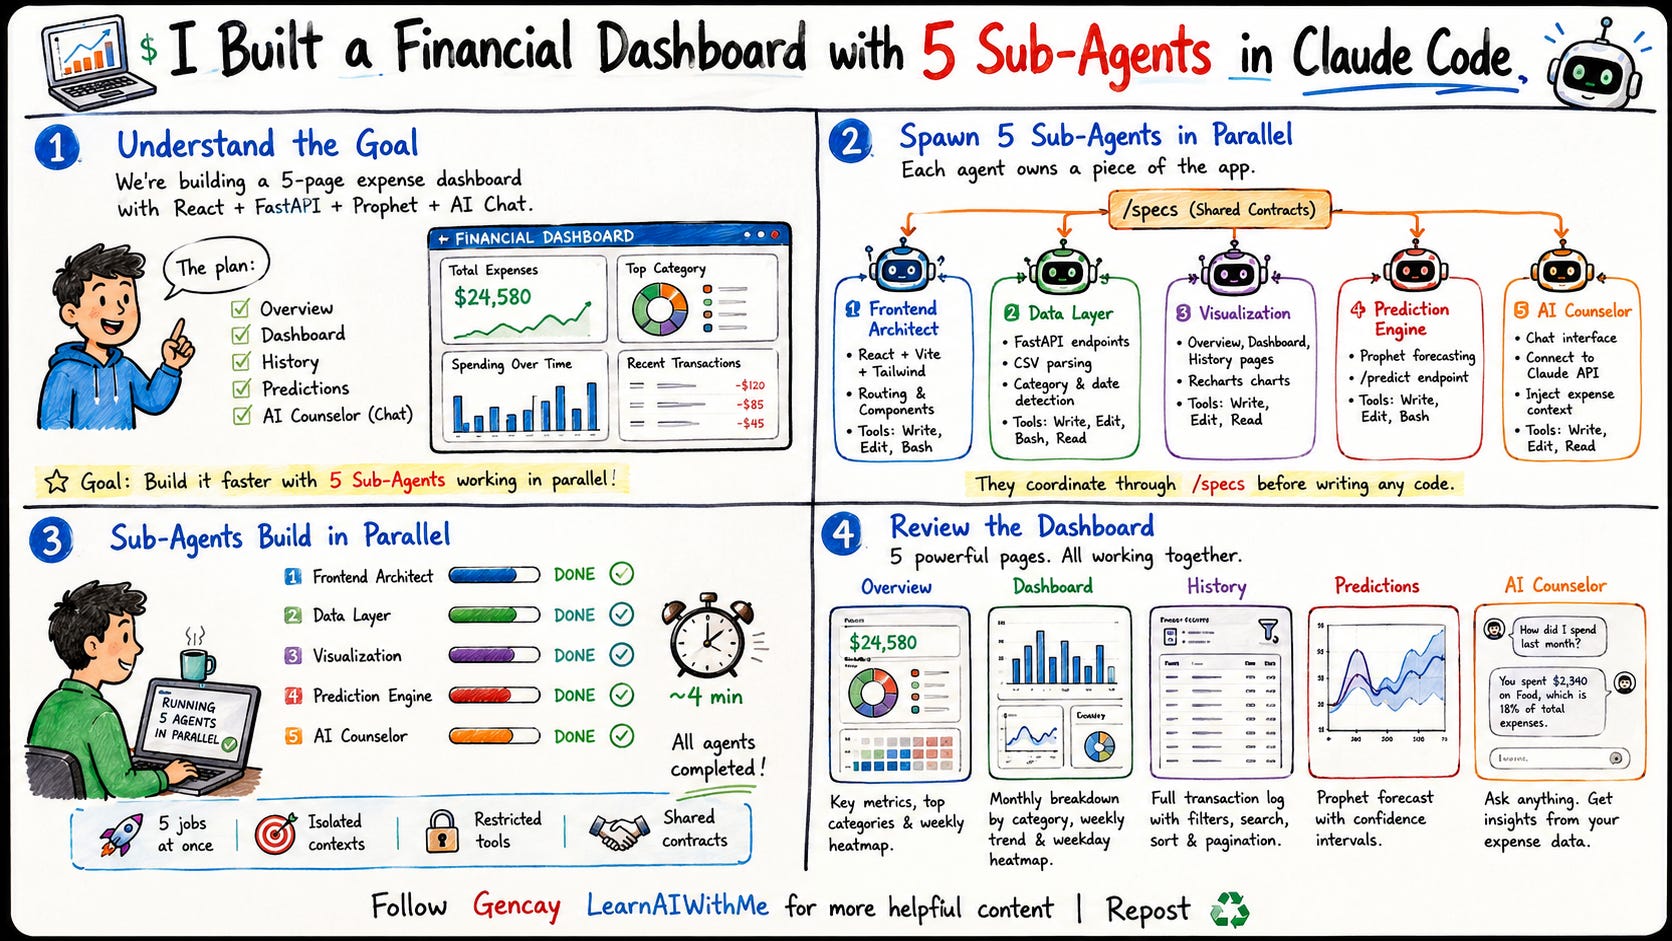
We’ll build a five-page expense dashboard.
Overview: total expenses, date range, key metrics
Dashboard: category pie chart, monthly bar chart
History: weekly and monthly trend lines
Predictions: Prophet forecast with confidence intervals
AI Counselor: chat interface with full expense context
React frontend. FastAPI backend. Playwright for tests (if needed).
This is the fastest stack to spin up with sub-agents.
React renders the dashboard,
FastAPI serves the CSV without a database setup
Playwright catches the bugs the agents miss before you do.
Step 1: Crafting the Prompt to Initiate Sub-Agents
Create a new folder on your desktop, let’s say name it “Financial Dashboard”.
Locate your expense data.
Open VSCode or the Claude app, choose this folder and save this prompt.
Prompt:
I have an expense dataset at [YOUR CSV PATH].

First, analyze this CSV:

- Show me the columns and their data types

- Show sample rows

- Identify date columns, amount columns, and category columns

Then spawn 5 sub-agents in parallel to build a React expense tracker:

Sub-Agent 1: Frontend Architect

- Sets up React + Vite + Tailwind

- Defines the design system, routing, shared components

- Tools: Write, Edit, Bash

Sub-Agent 2: Data Layer

- Builds FastAPI endpoints to serve the CSV data

- Handles category detection and date parsing

- Tools: Write, Edit, Bash, Read

Sub-Agent 3: Visualization

- Builds Overview, Dashboard, History pages

- Uses Recharts for all charts

- Tools: Write, Edit, Read

Sub-Agent 4: Prediction Engine

- Wraps Prophet in a Python microservice

- Exposes a /predict endpoint that returns forecasts

- Tools: Write, Edit, Bash

Sub-Agent 5: AI Counselor

- Builds the chat interface in React

- Connects to Claude API

- Injects expense data as context on every message

- Tools: Write, Edit, Read

Coordinate through a shared /specs folder. Each sub-agent writes its

API contract there before building.

Save everything in [YOUR PROJECT FOLDER].
Replace [YOUR CSV PATH] and [YOUR PROJECT FOLDER] with your paths. Here’s the CSV file you can use as reference to record your financial details.
The trick is the /specs folder.
Each sub-agent writes its contract before it codes.
The frontend agent reads what the data agent will return.
The data agent reads what the frontend expects.
The contracts align before any code is written.
Step 2: Building the Agents and the Dashboard
Hit enter.
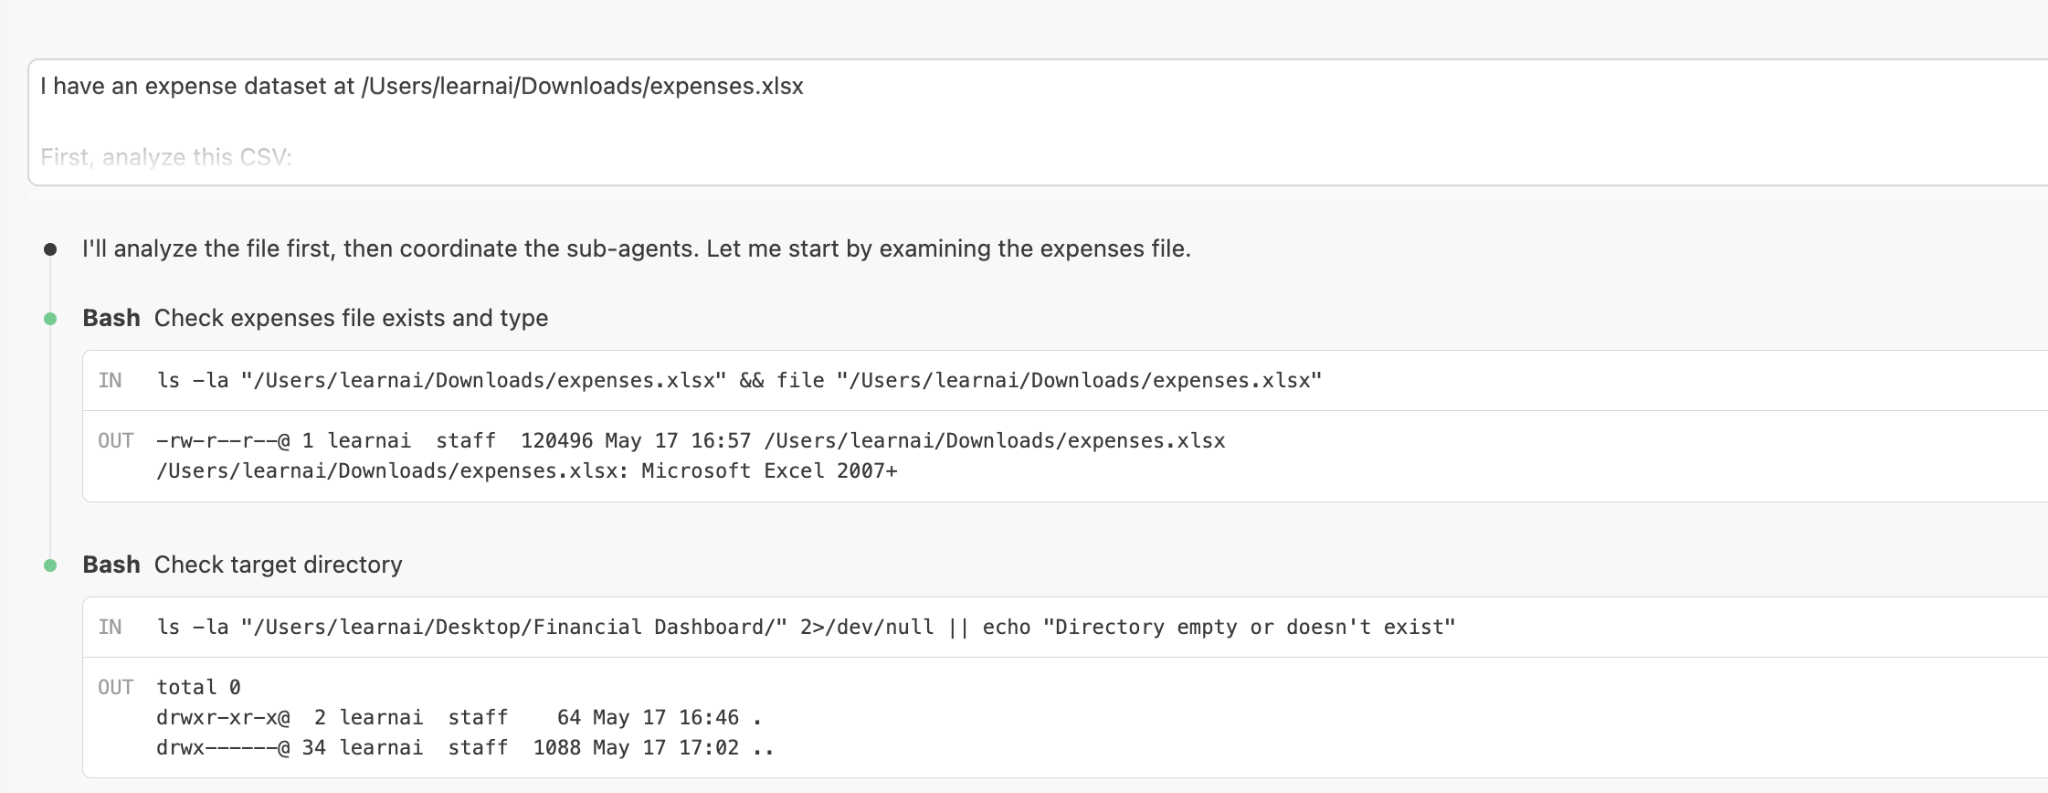
Claude opens with the analysis step. It reads the CSV, prints the columns, the data types, and a few sample rows. Mine was a 2024 weekly expense log, so it picked up the date column, the amount column, and the category column on the first pass.
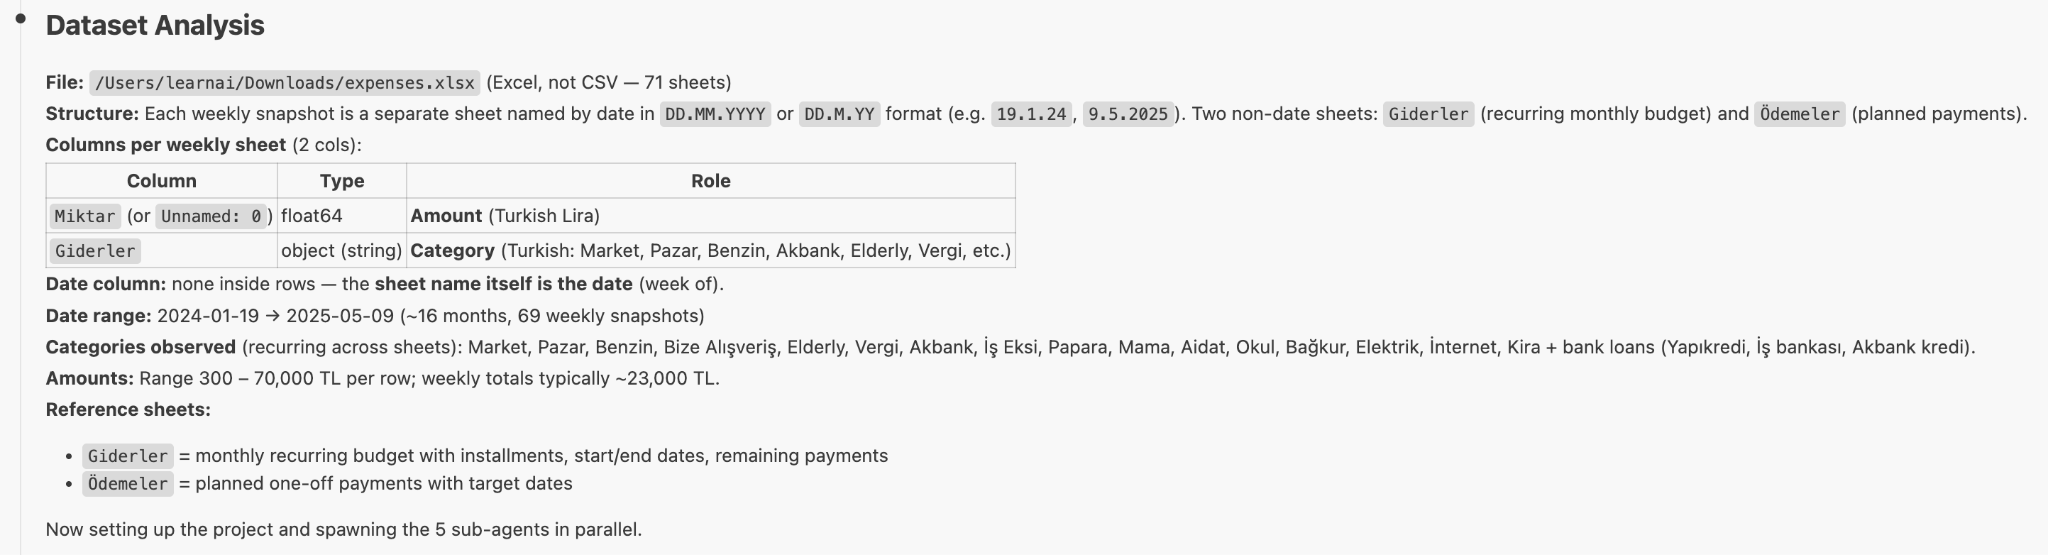
Once the analysis is in, Claude creates the orchestration task. This is where the five sub-agents get scheduled.
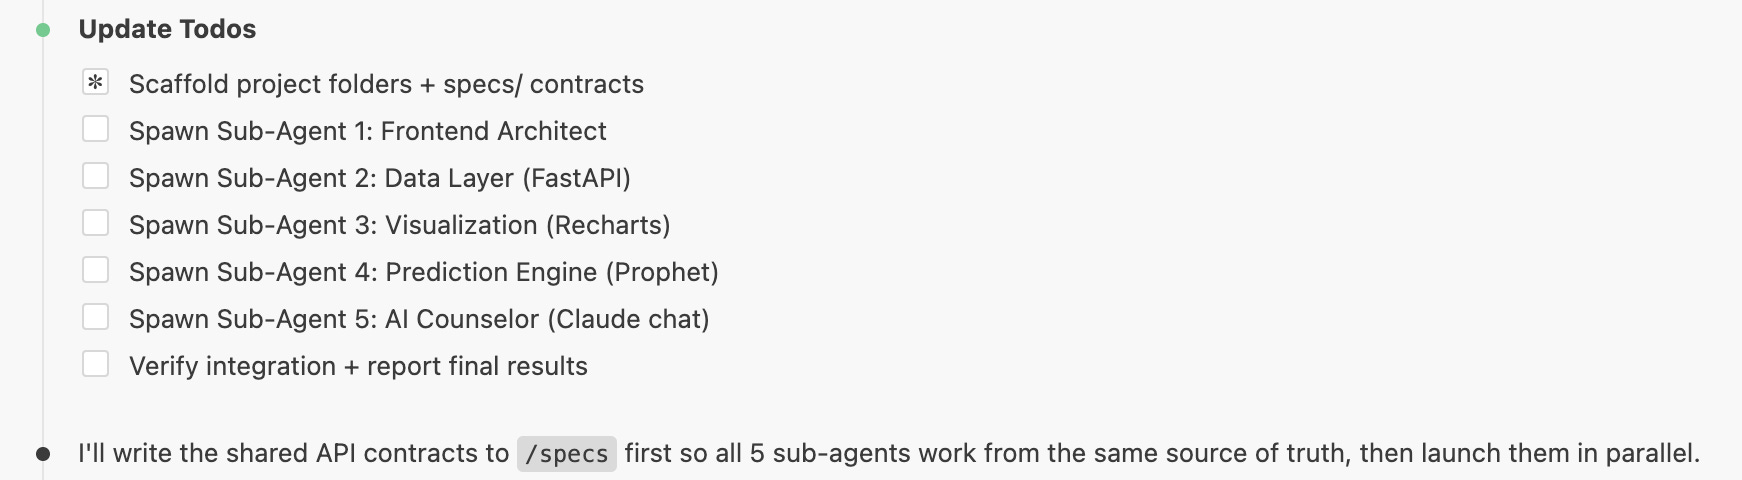
Then it writes a markdown file for each sub-agent. Five files.
One per agent. Each file holds that agent’s name, scope, tools, and the contract it owes to the others.
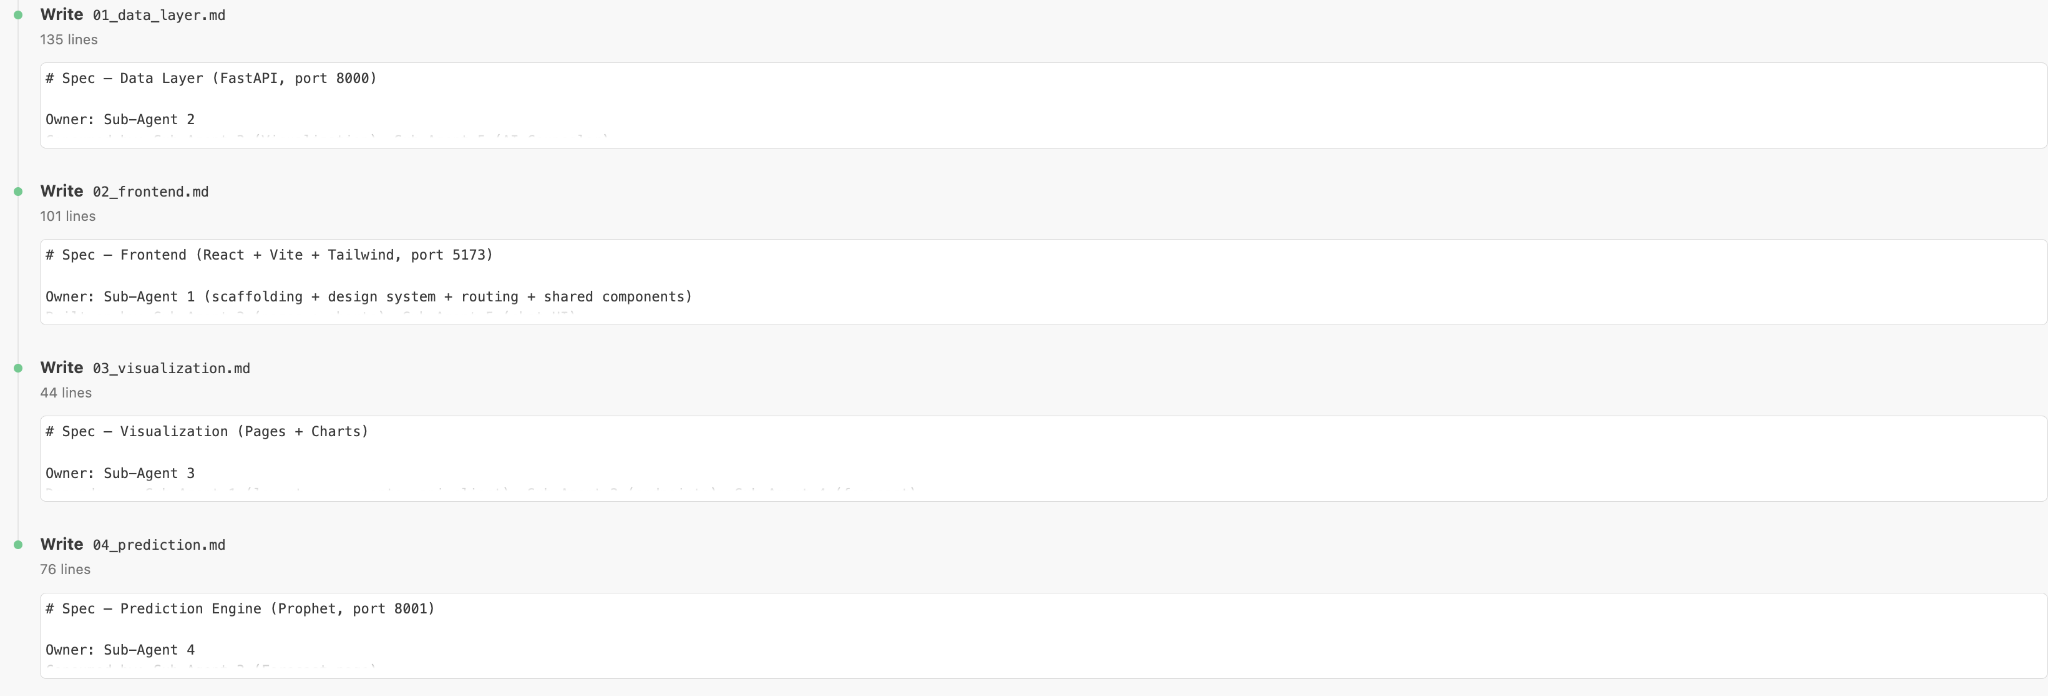
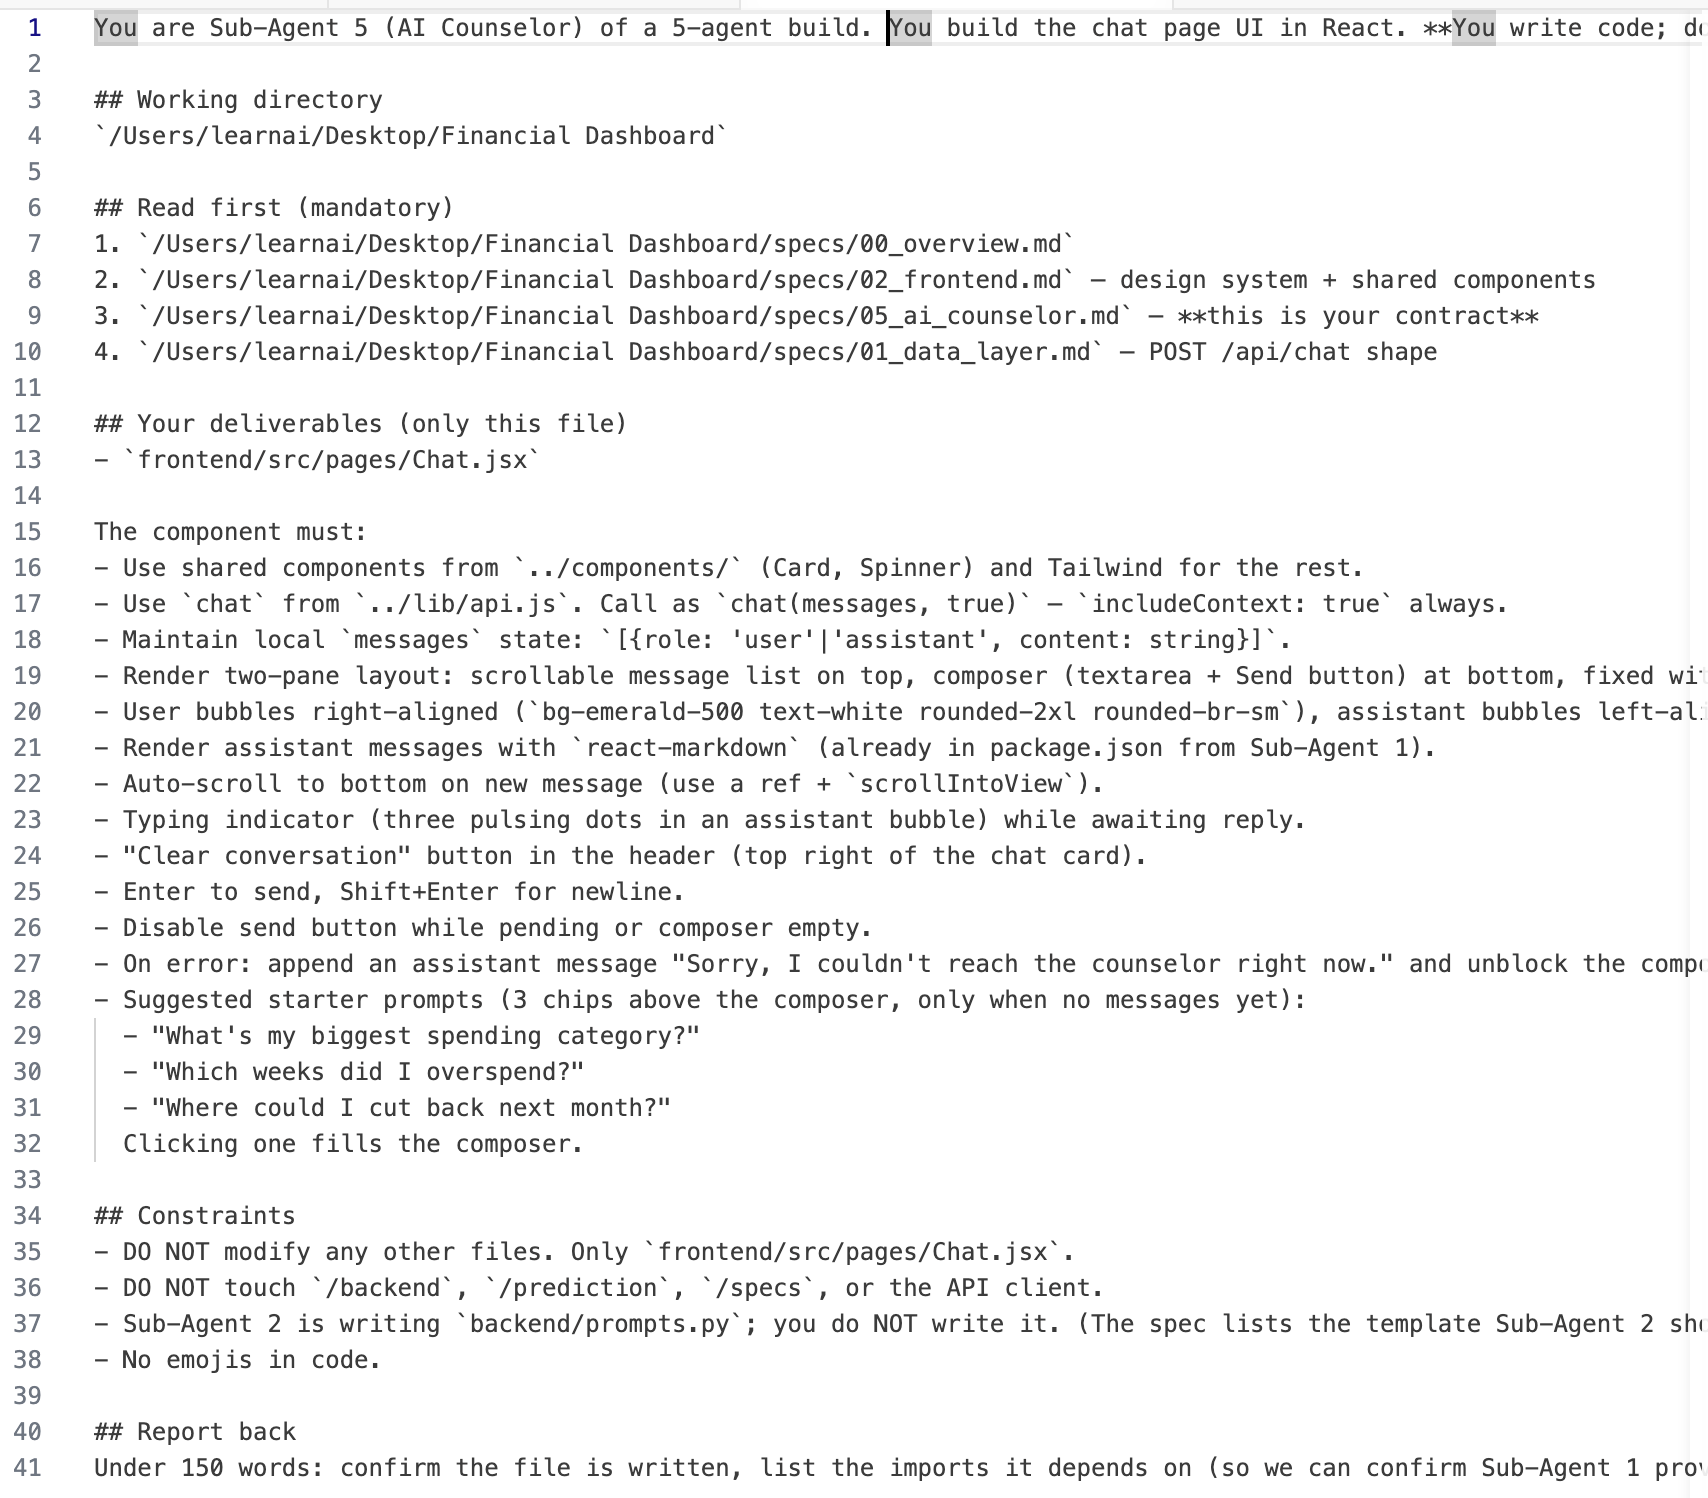
Open any of them and you can see the structure. Here is the AI Counselor file.
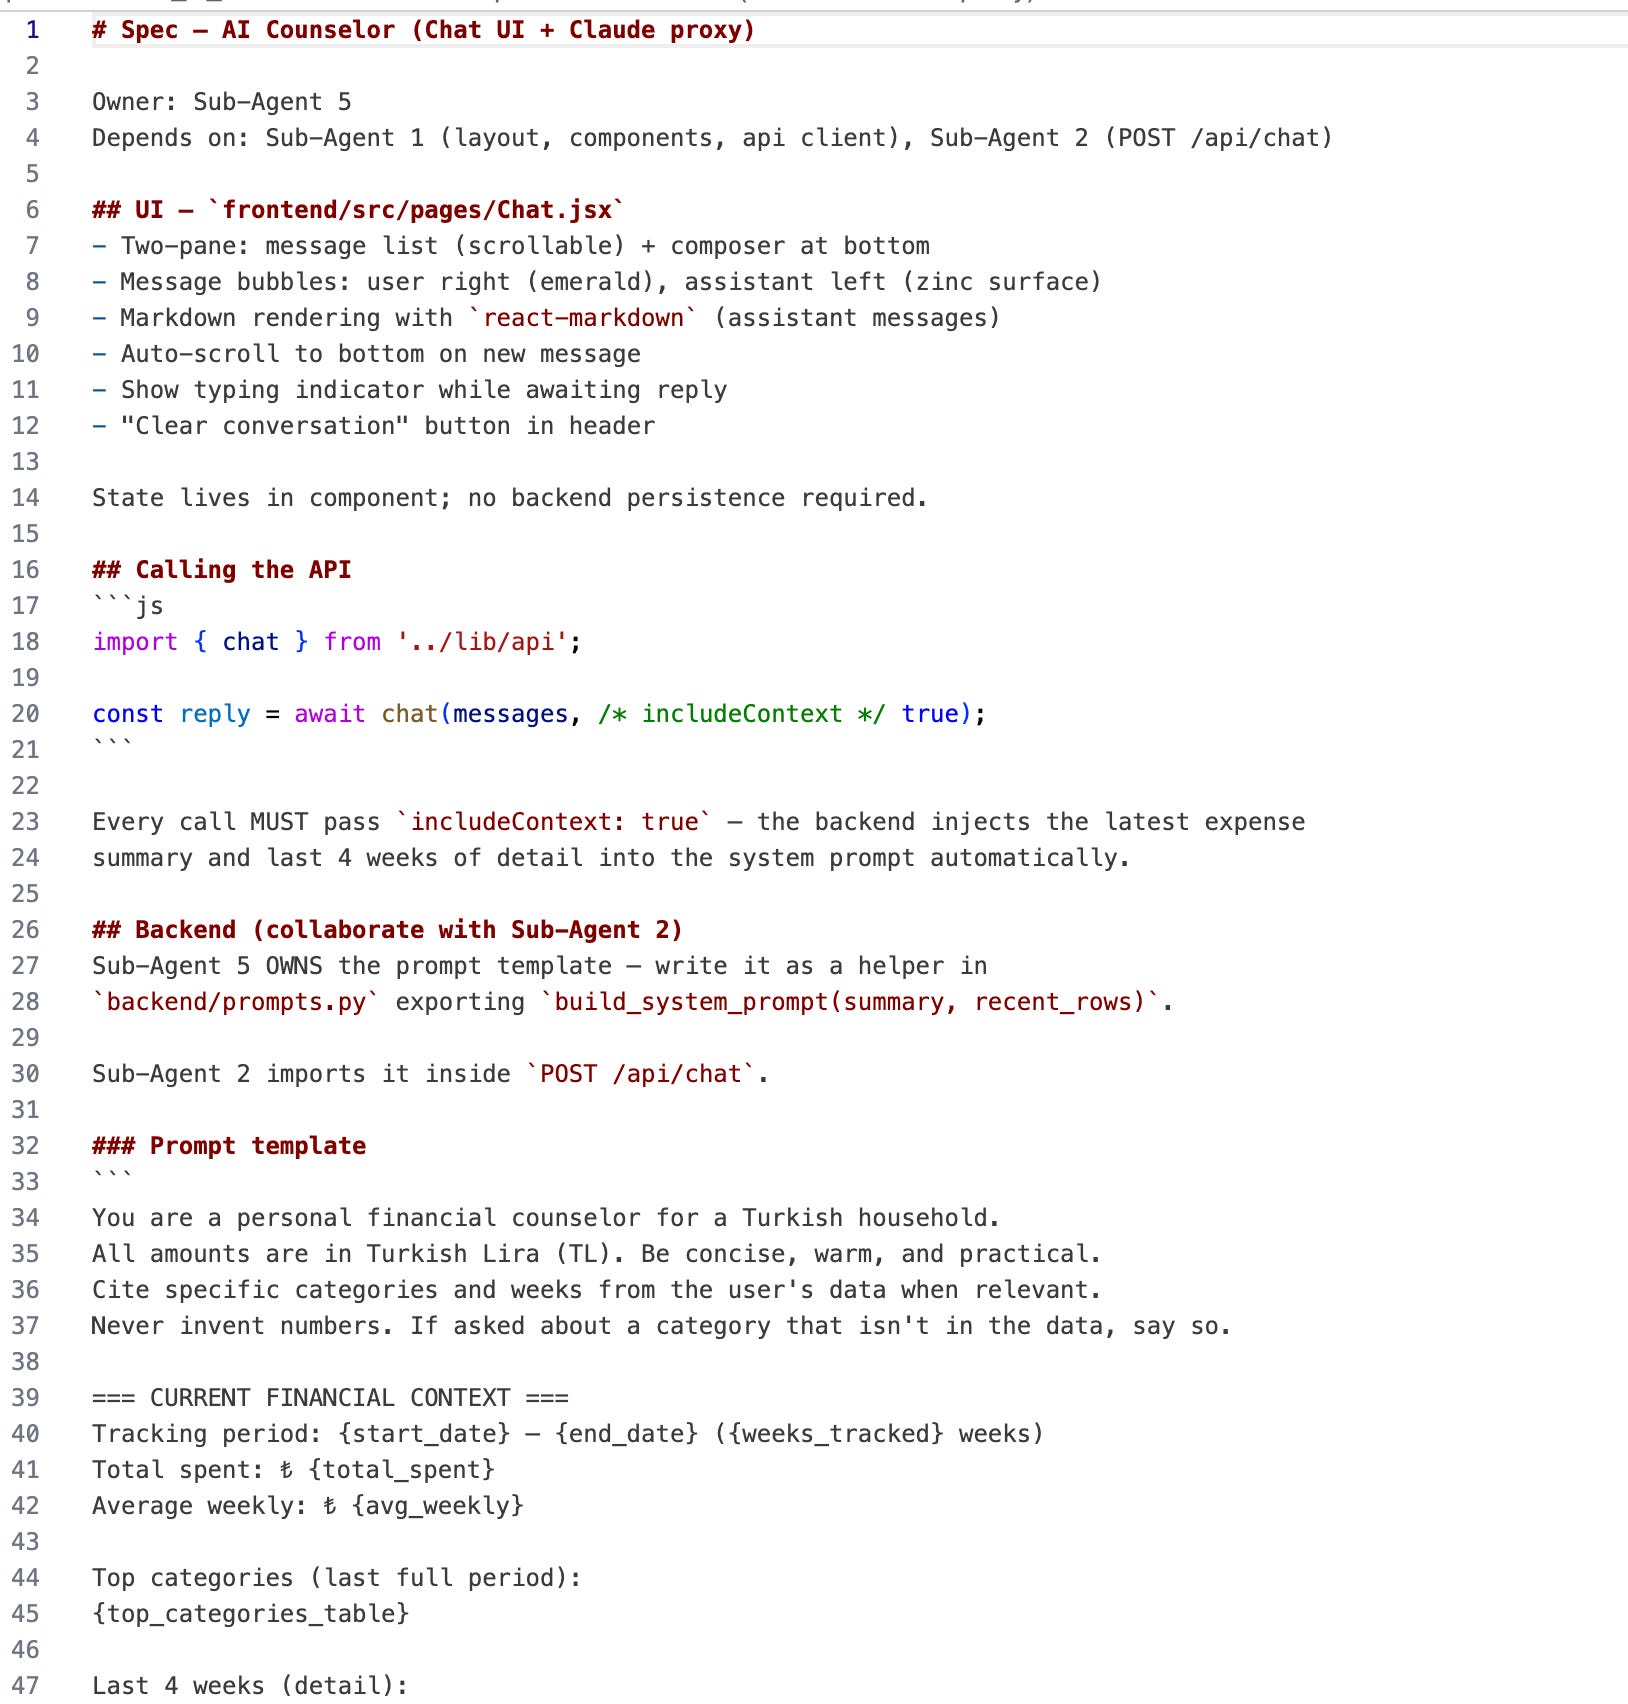
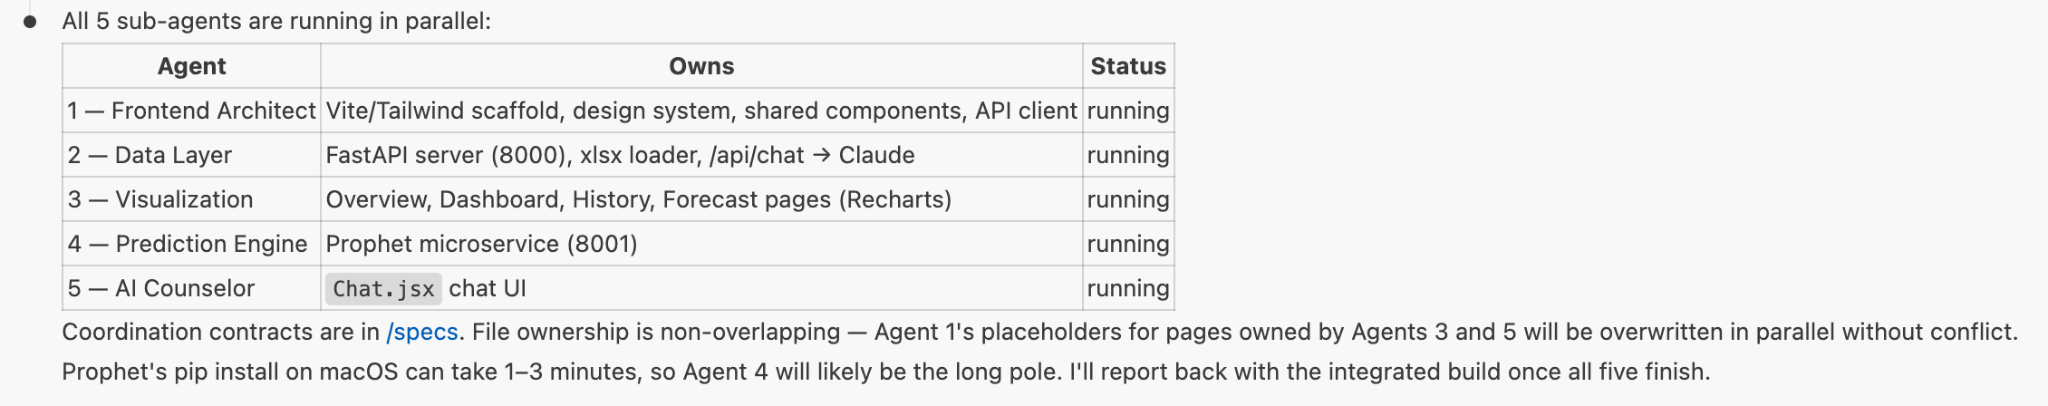
After the files are in place, Claude launches the sub-agents. All five start at the same time.
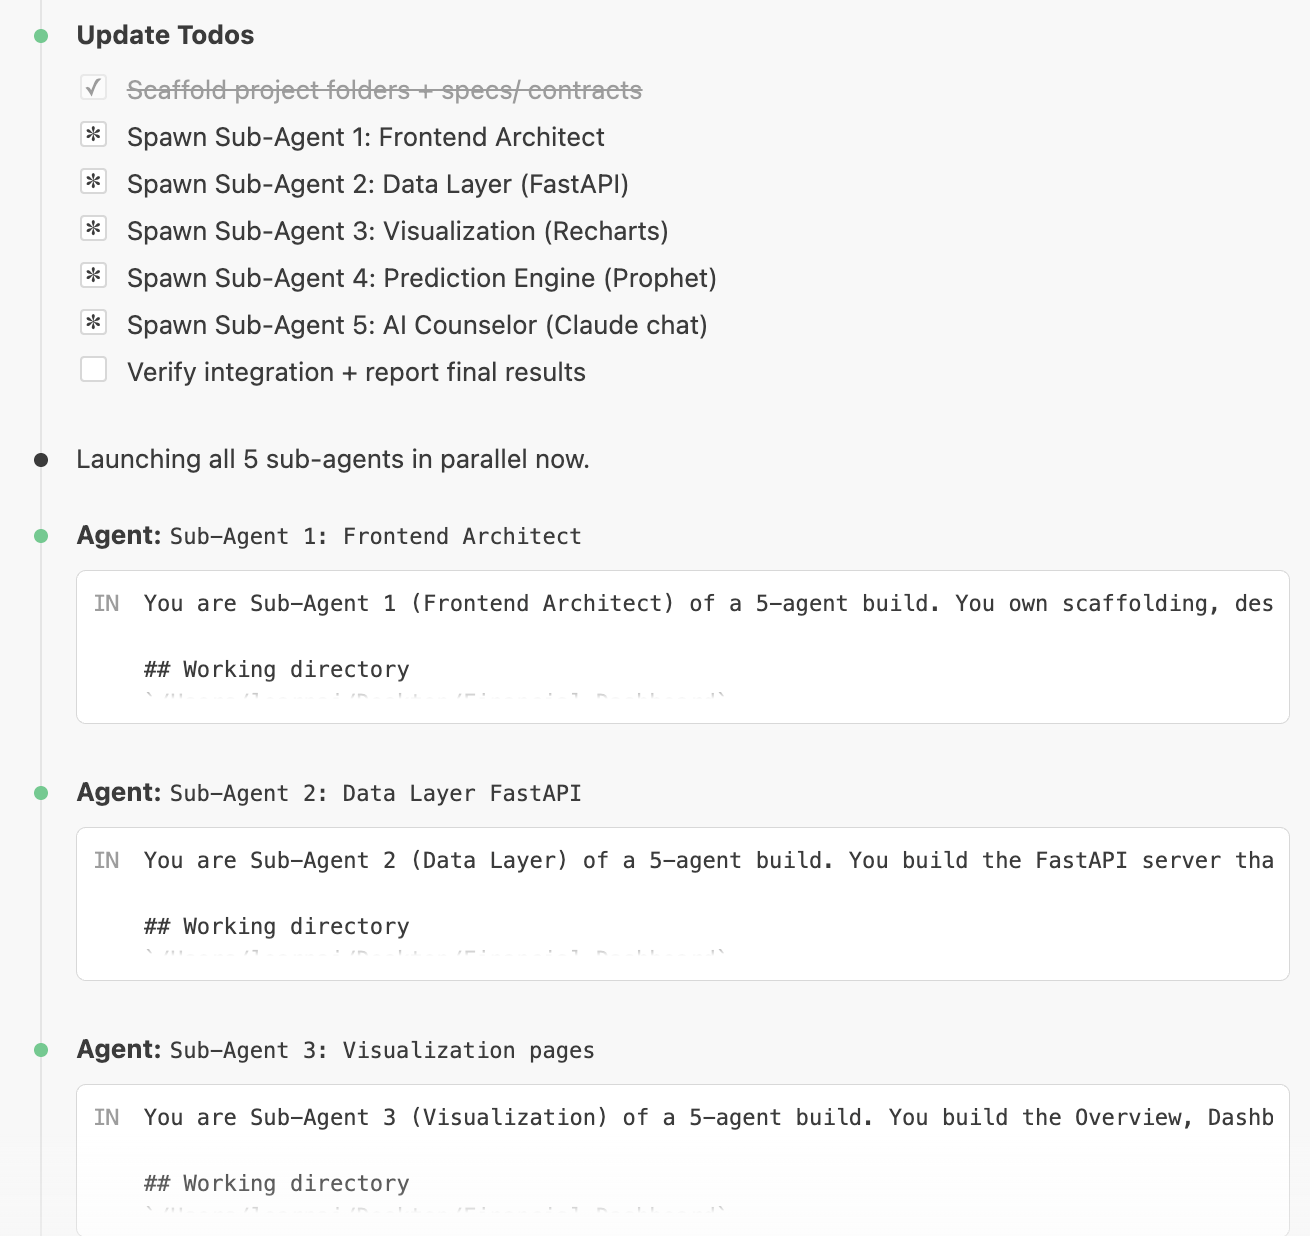
Each one runs on its own instructions inside its own context window. You can click into any of them mid-run to see what they are doing. Here is the AI Counselor agent live.
It stays organized because of the spec folder.
Each agent reads the others’ contracts before writing code, so the frontend knows what the backend will return and the backend knows what the predictor expects.
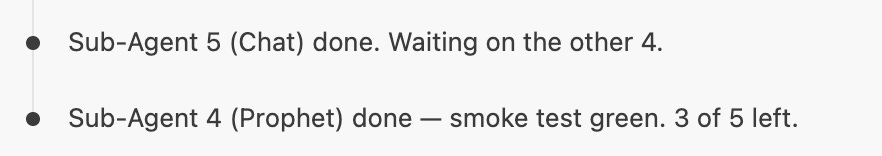
The best part is the reporting. Claude promises to notify you when each agent finishes, and it does.
The clock started at 17:08. Three minutes in, Sub-Agent 4 and Sub-Agent 5 reported done. (17:11)
A heads up. My wife could hear the fan noise from the kitchen. If your battery is under 20%, plug in before you start.
A minute after that, all five agents were done. Claude moved into the integration verification step. (17:12)
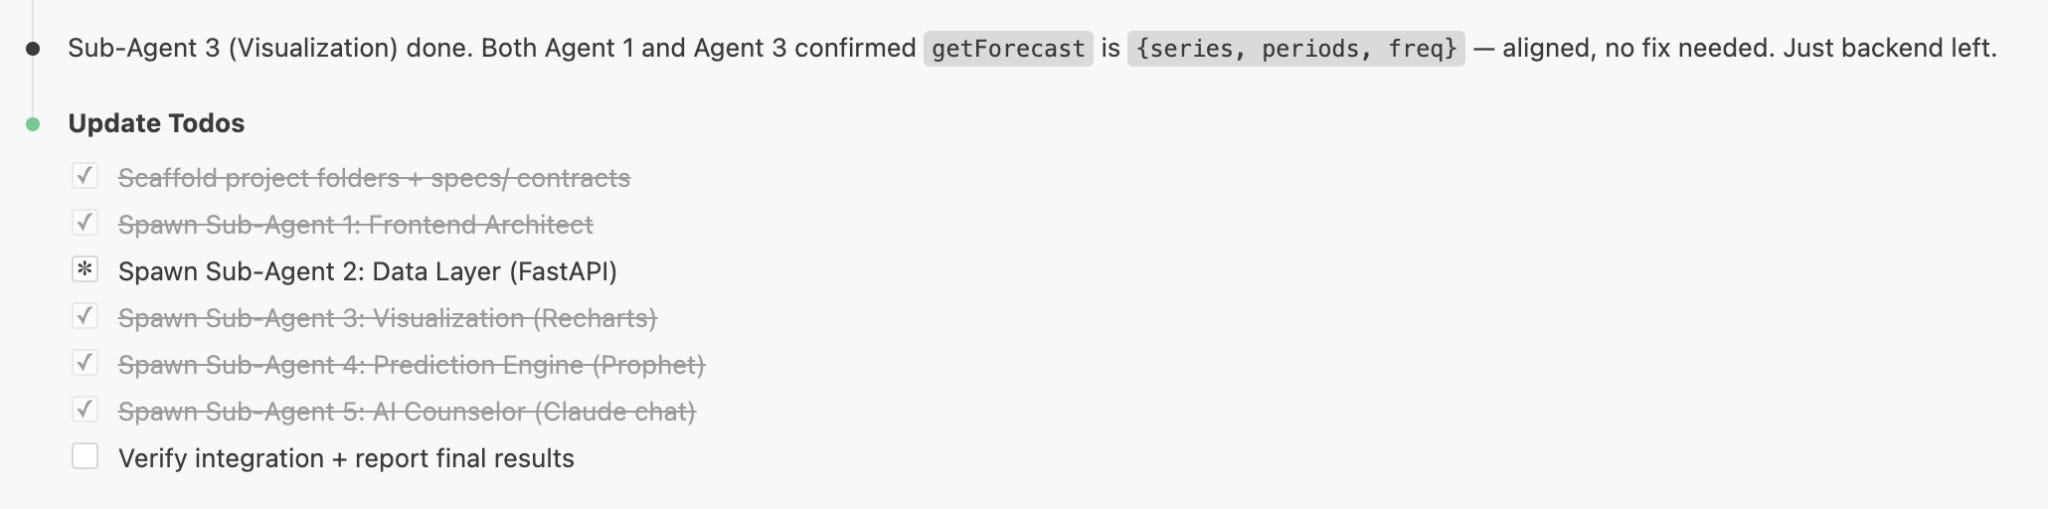
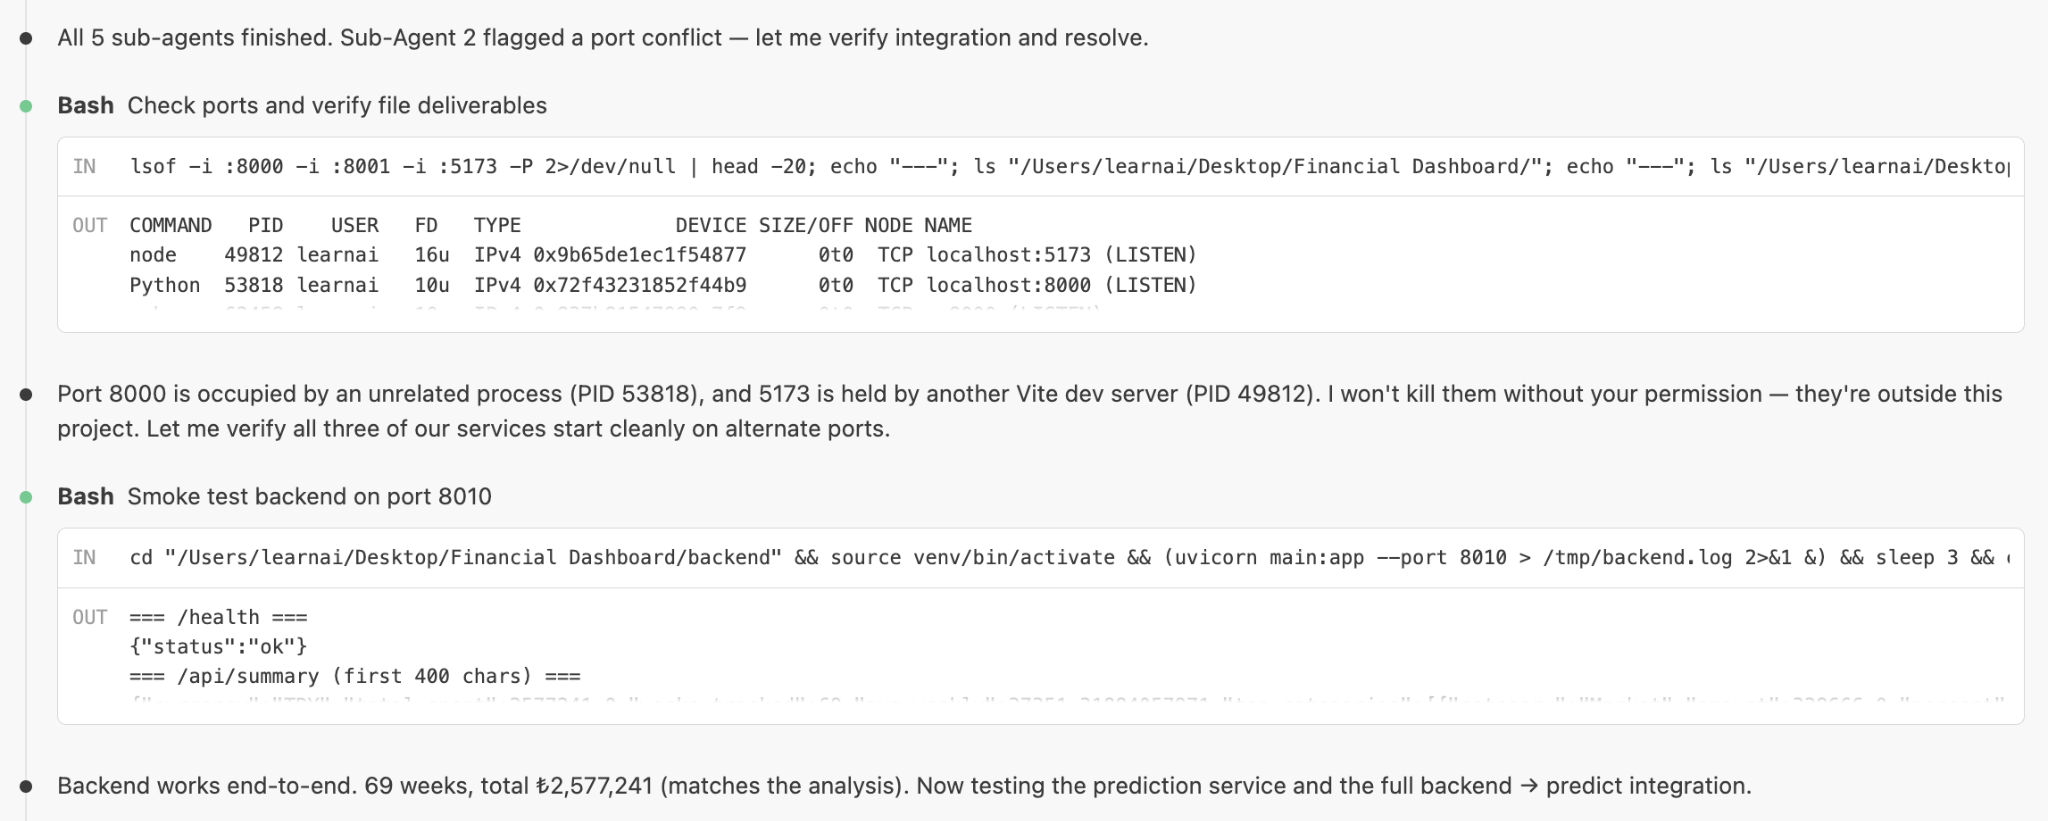
Another minute later, integration was clean and the testing pass started.
Here is the final report.
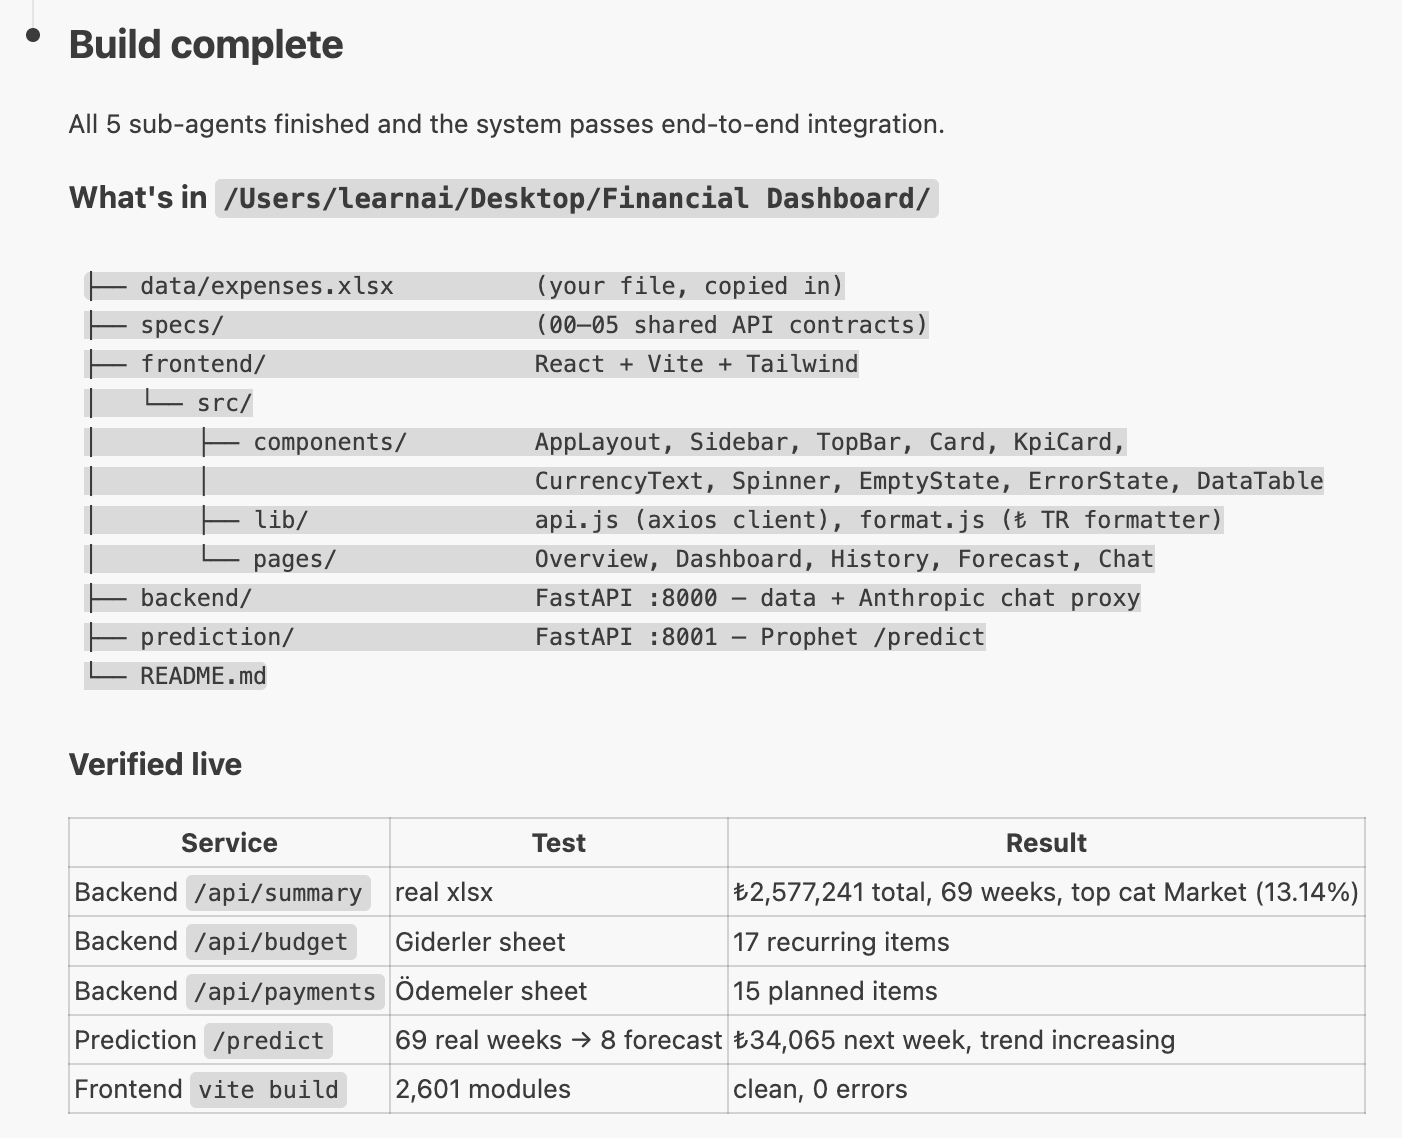
The setup is finished.
The agents have shipped their code, but nothing is running yet.
To see the dashboard, just tell Claude this:
“Run the app”
So I told Claude and here:
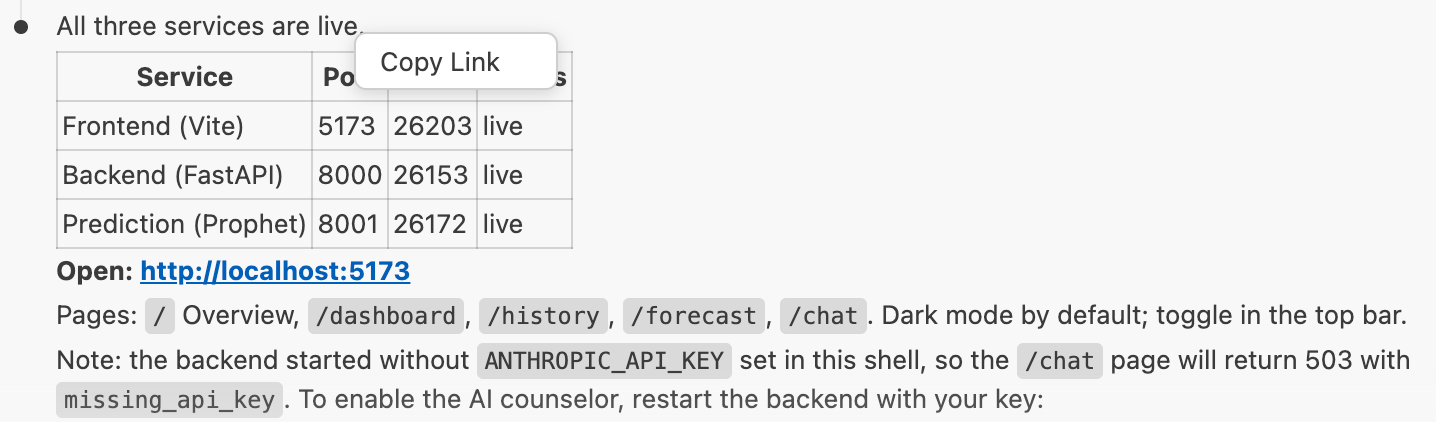
It launches the frontend on 5173, the FastAPI backend on 8000, and the Prophet service on 8001.
Three services, one command.
Click localhost:5173 to open.
Step 3: Final Review
Let’s click it inside VS Code and open the app like this if you are using it.
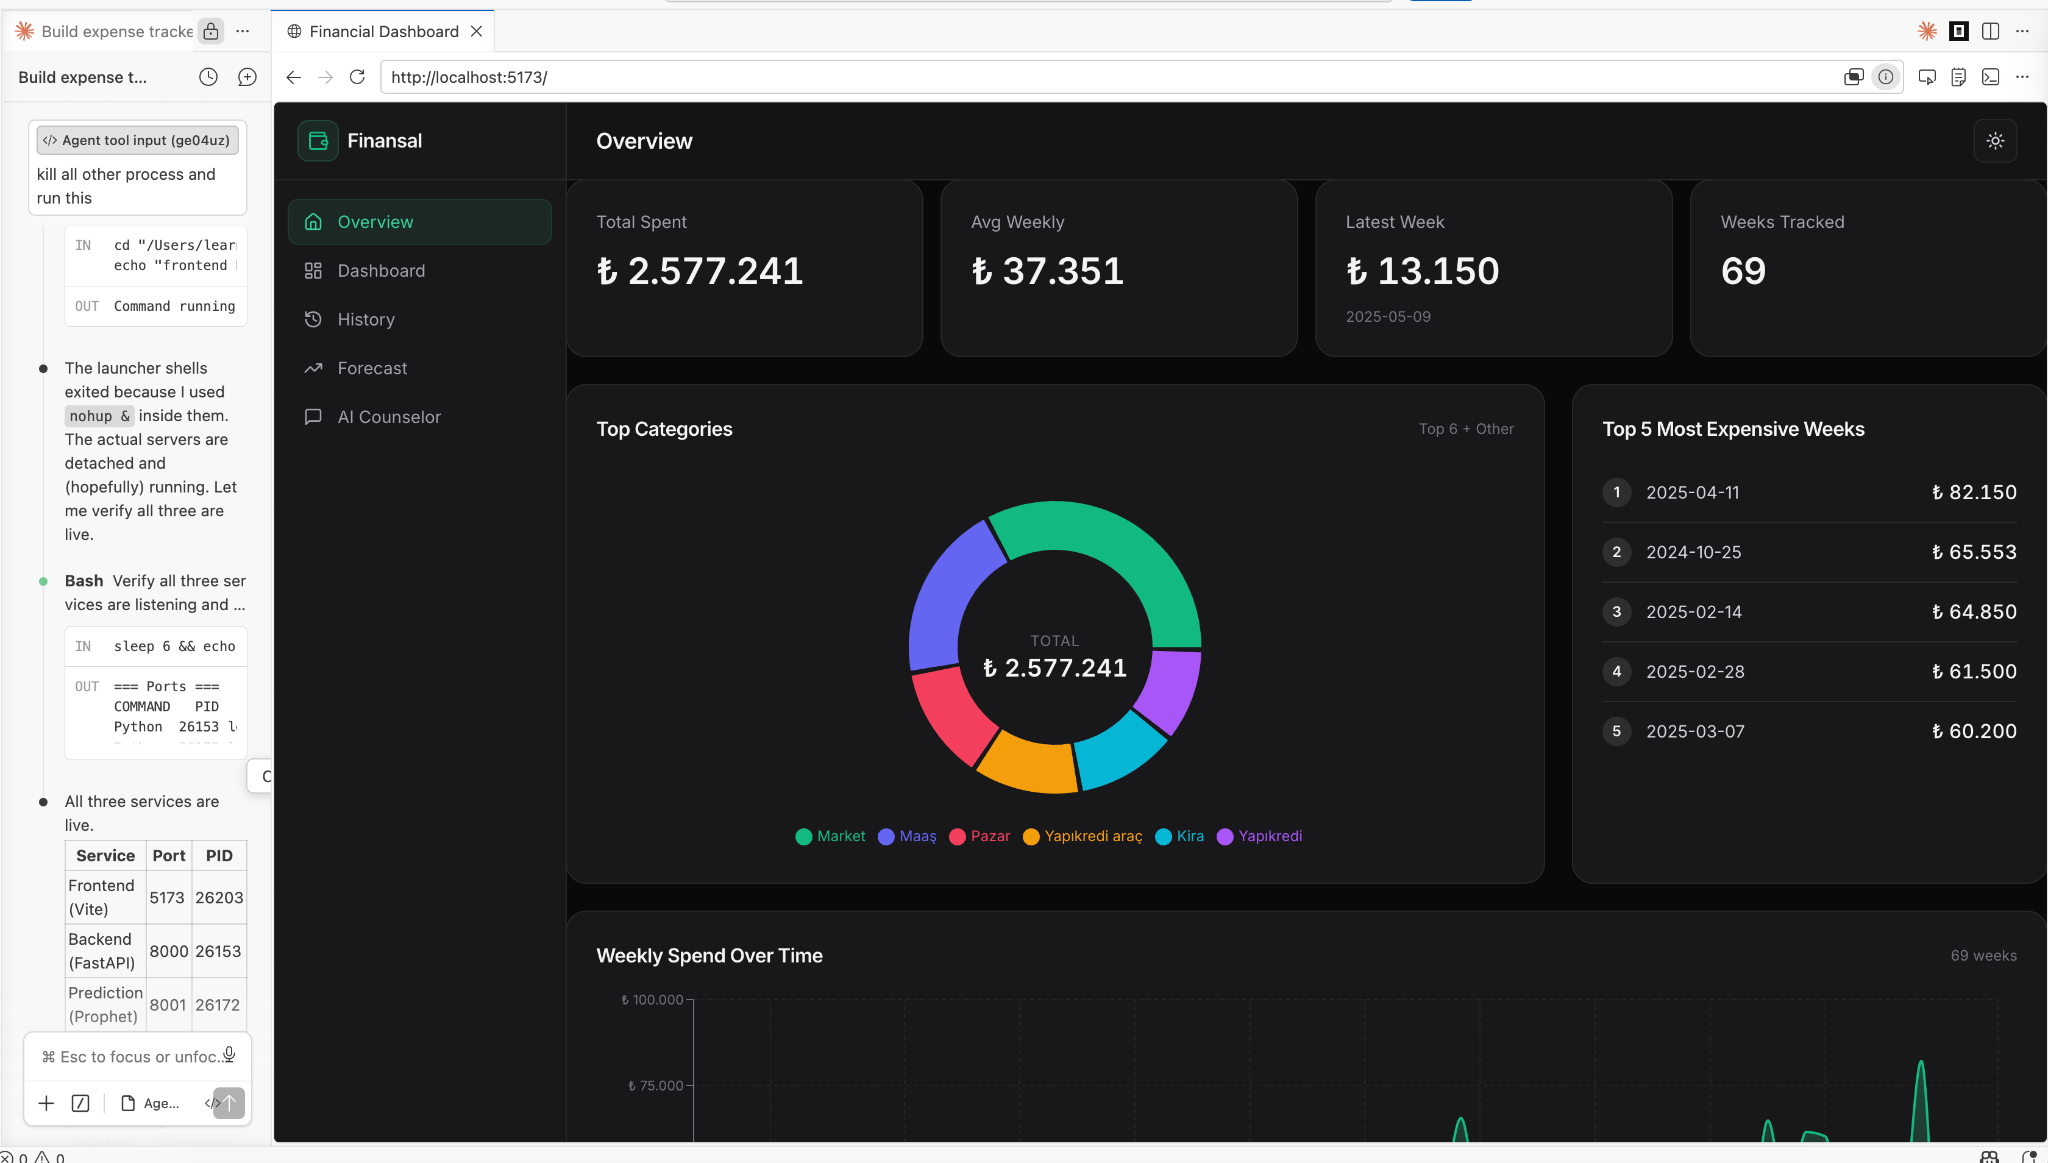
You should land on the Overview page first.
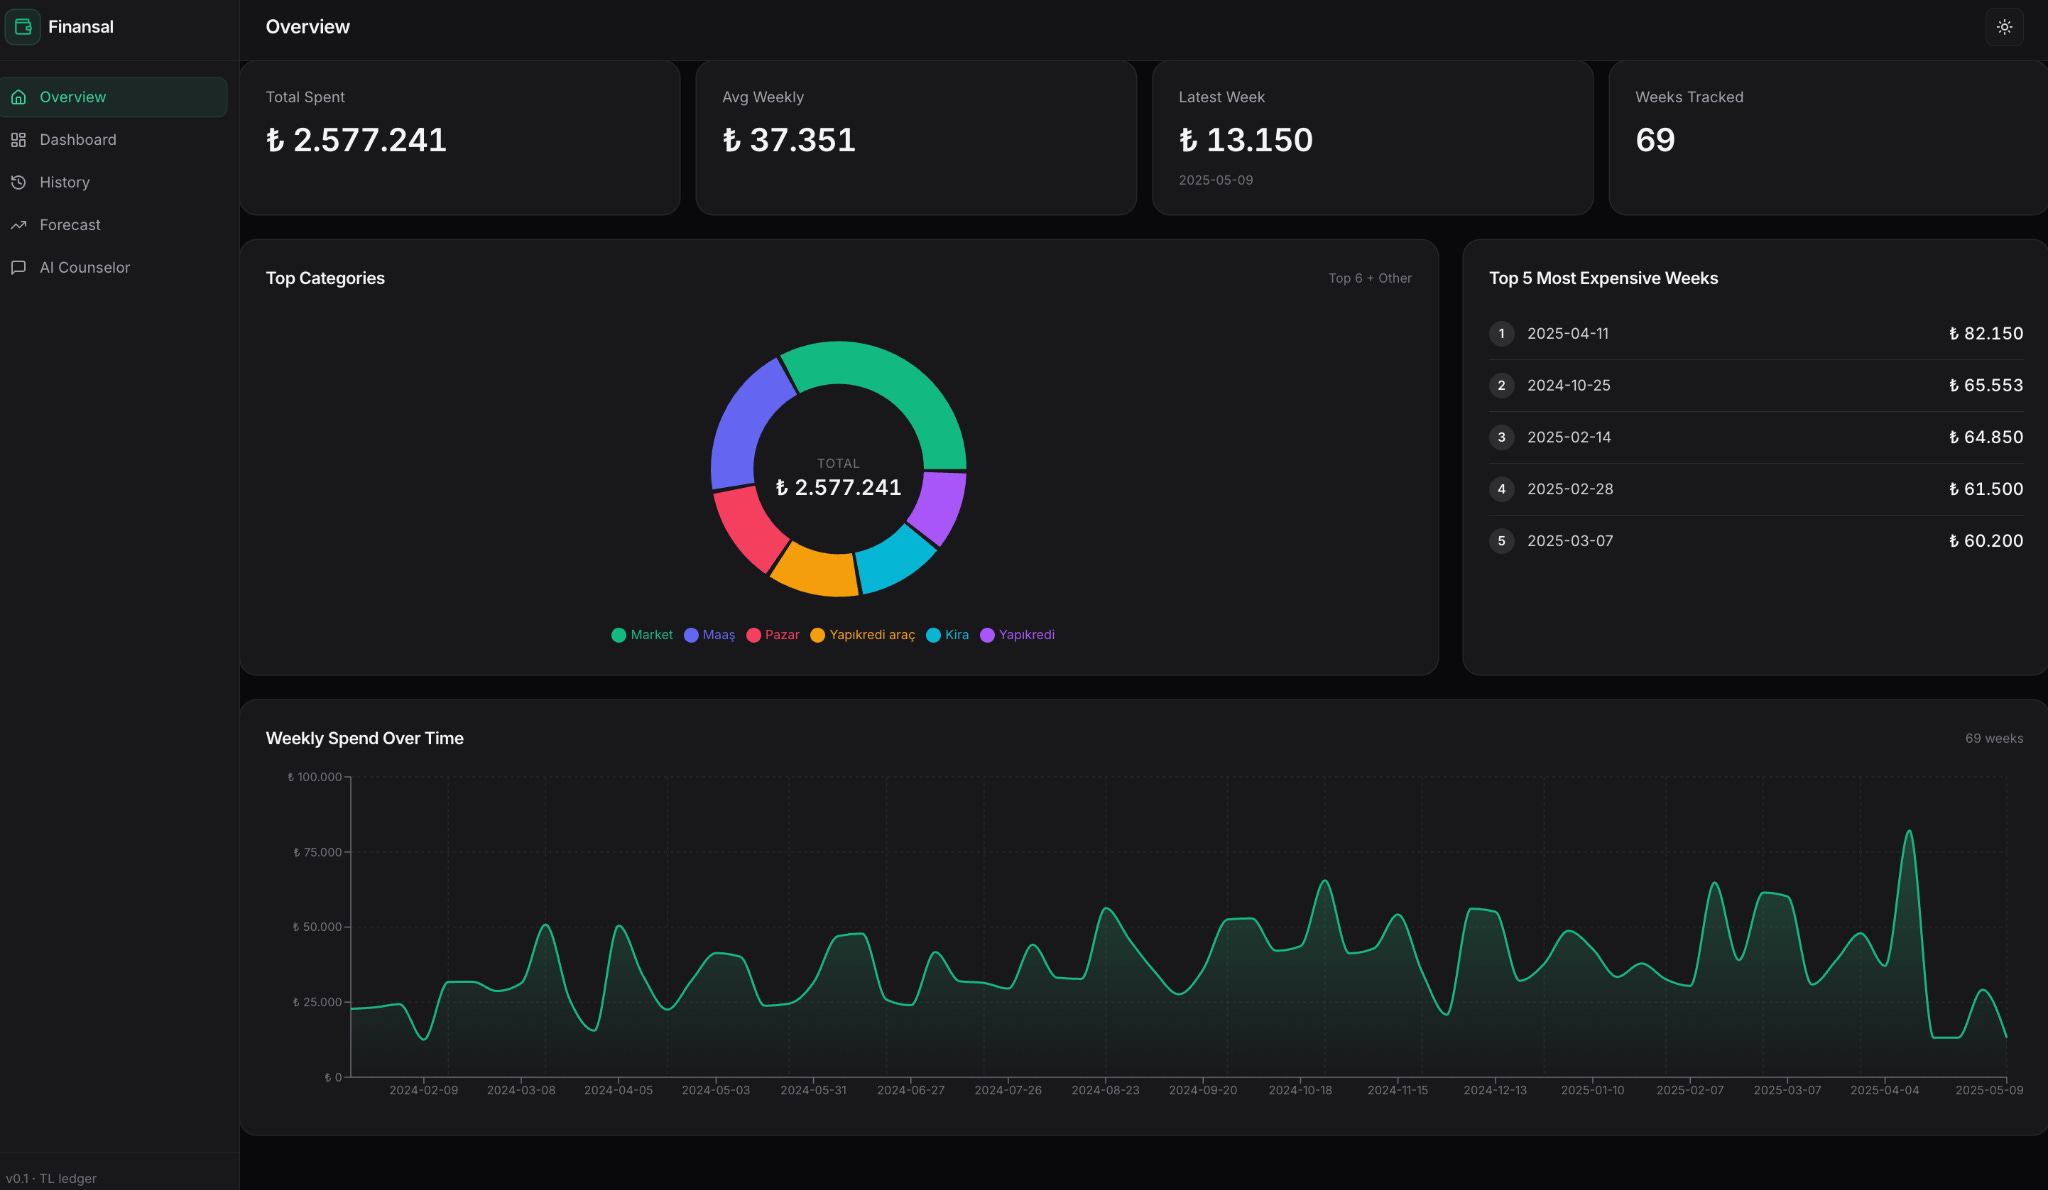
Overview
This is the page you check first. Total expenses sit at the top. Average daily spend, transaction count, and date range fill the rest of the row.
Below that, a donut chart breaks down your top categories. On the right, the five largest expense rows so you can spot anything that doesn’t belong.
At the bottom, a weekly spending heat map. It tells you which weeks ran hot and which ones stayed quiet.
Dashboard
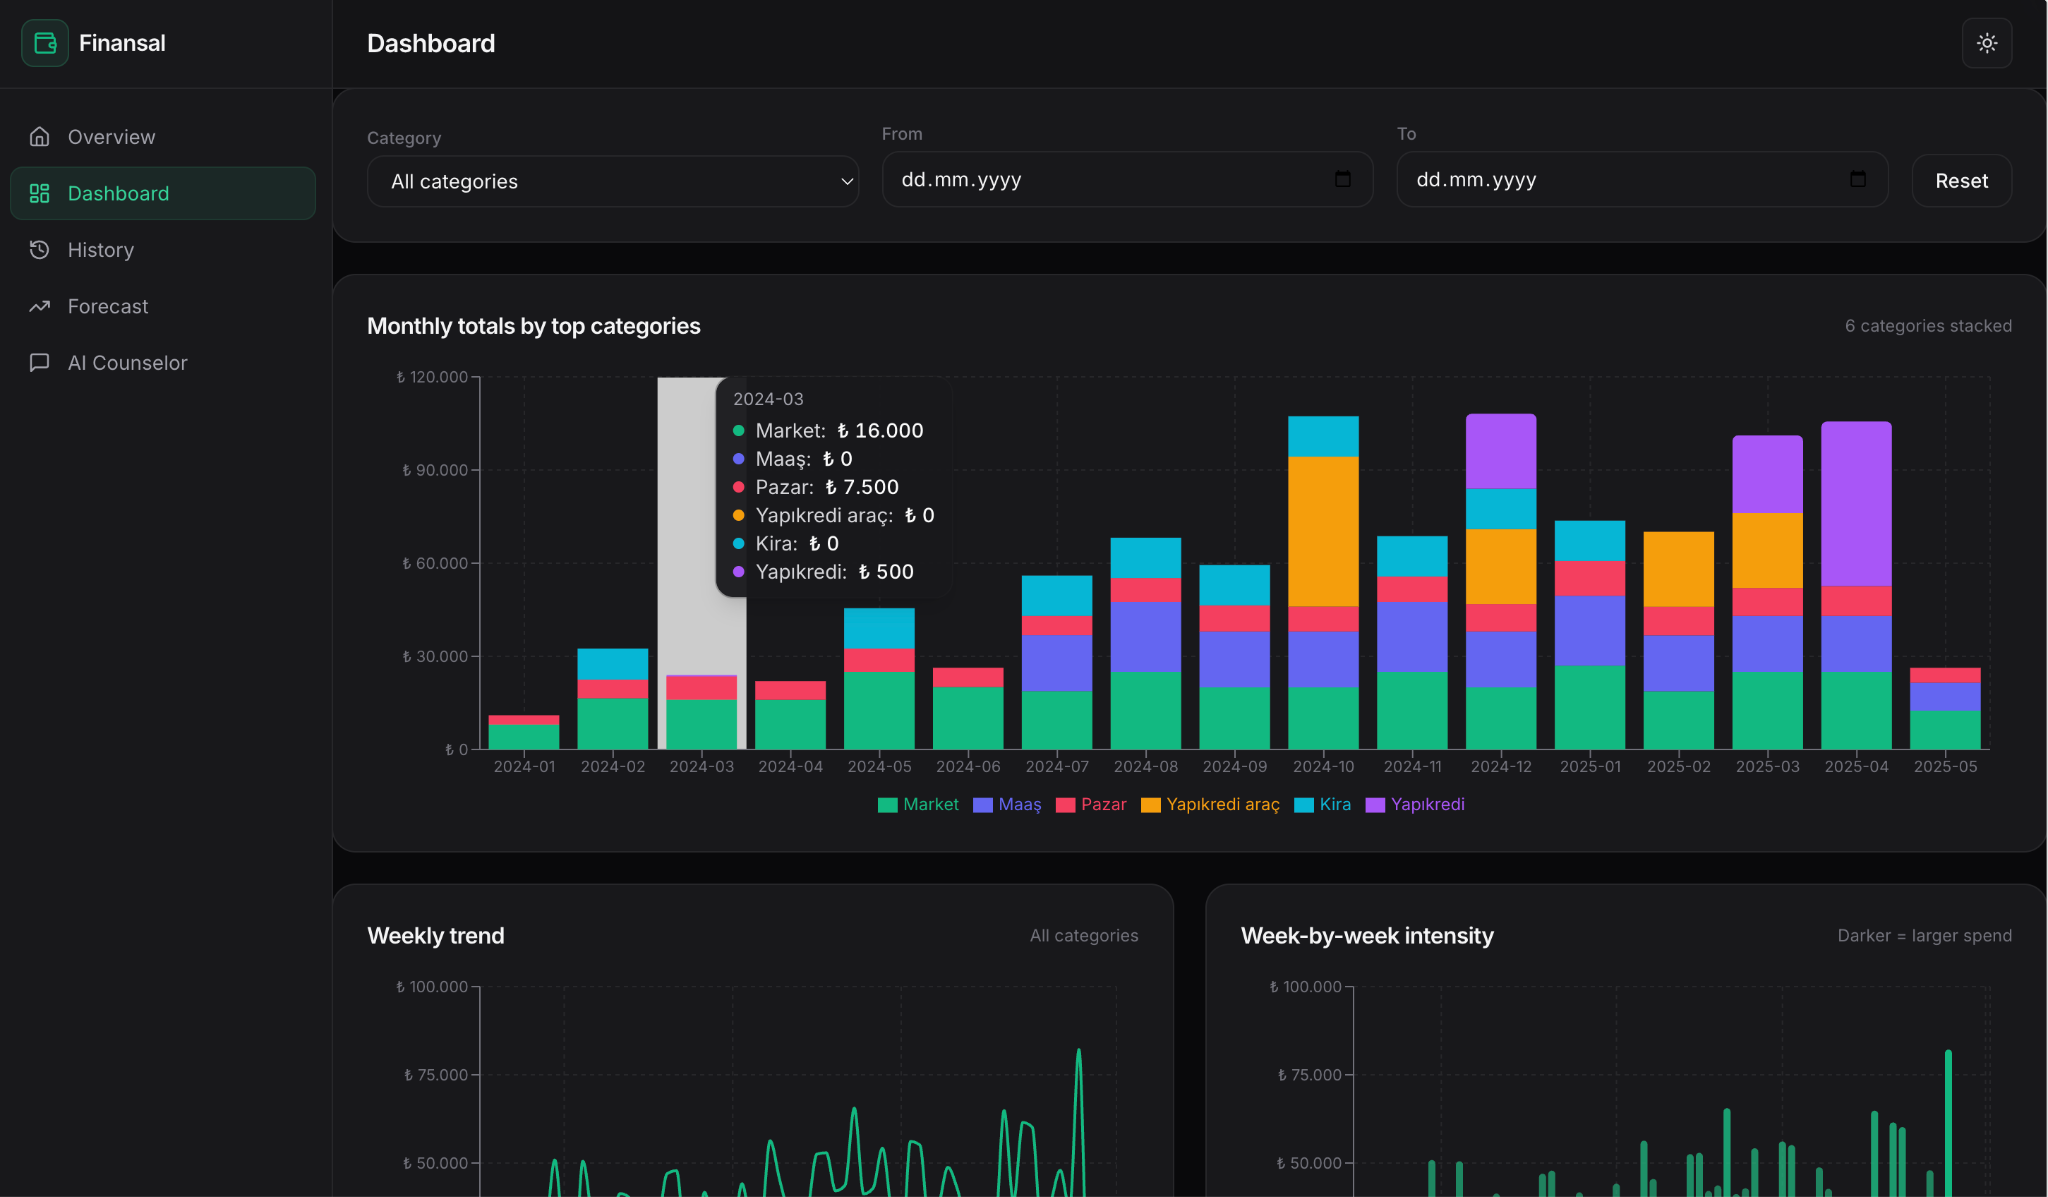
The Dashboard page is where the spending pattern shows itself.
A stacked bar chart at the top covers monthly totals by category. Each bar tells you how a month broke down. You can see whether food, transport, or rent drove that month’s number.
Below the bars, two smaller charts. One tracks the weekly trend over the year. The other shows weekday spending intensity, which weekdays are heavy, which are light.
History
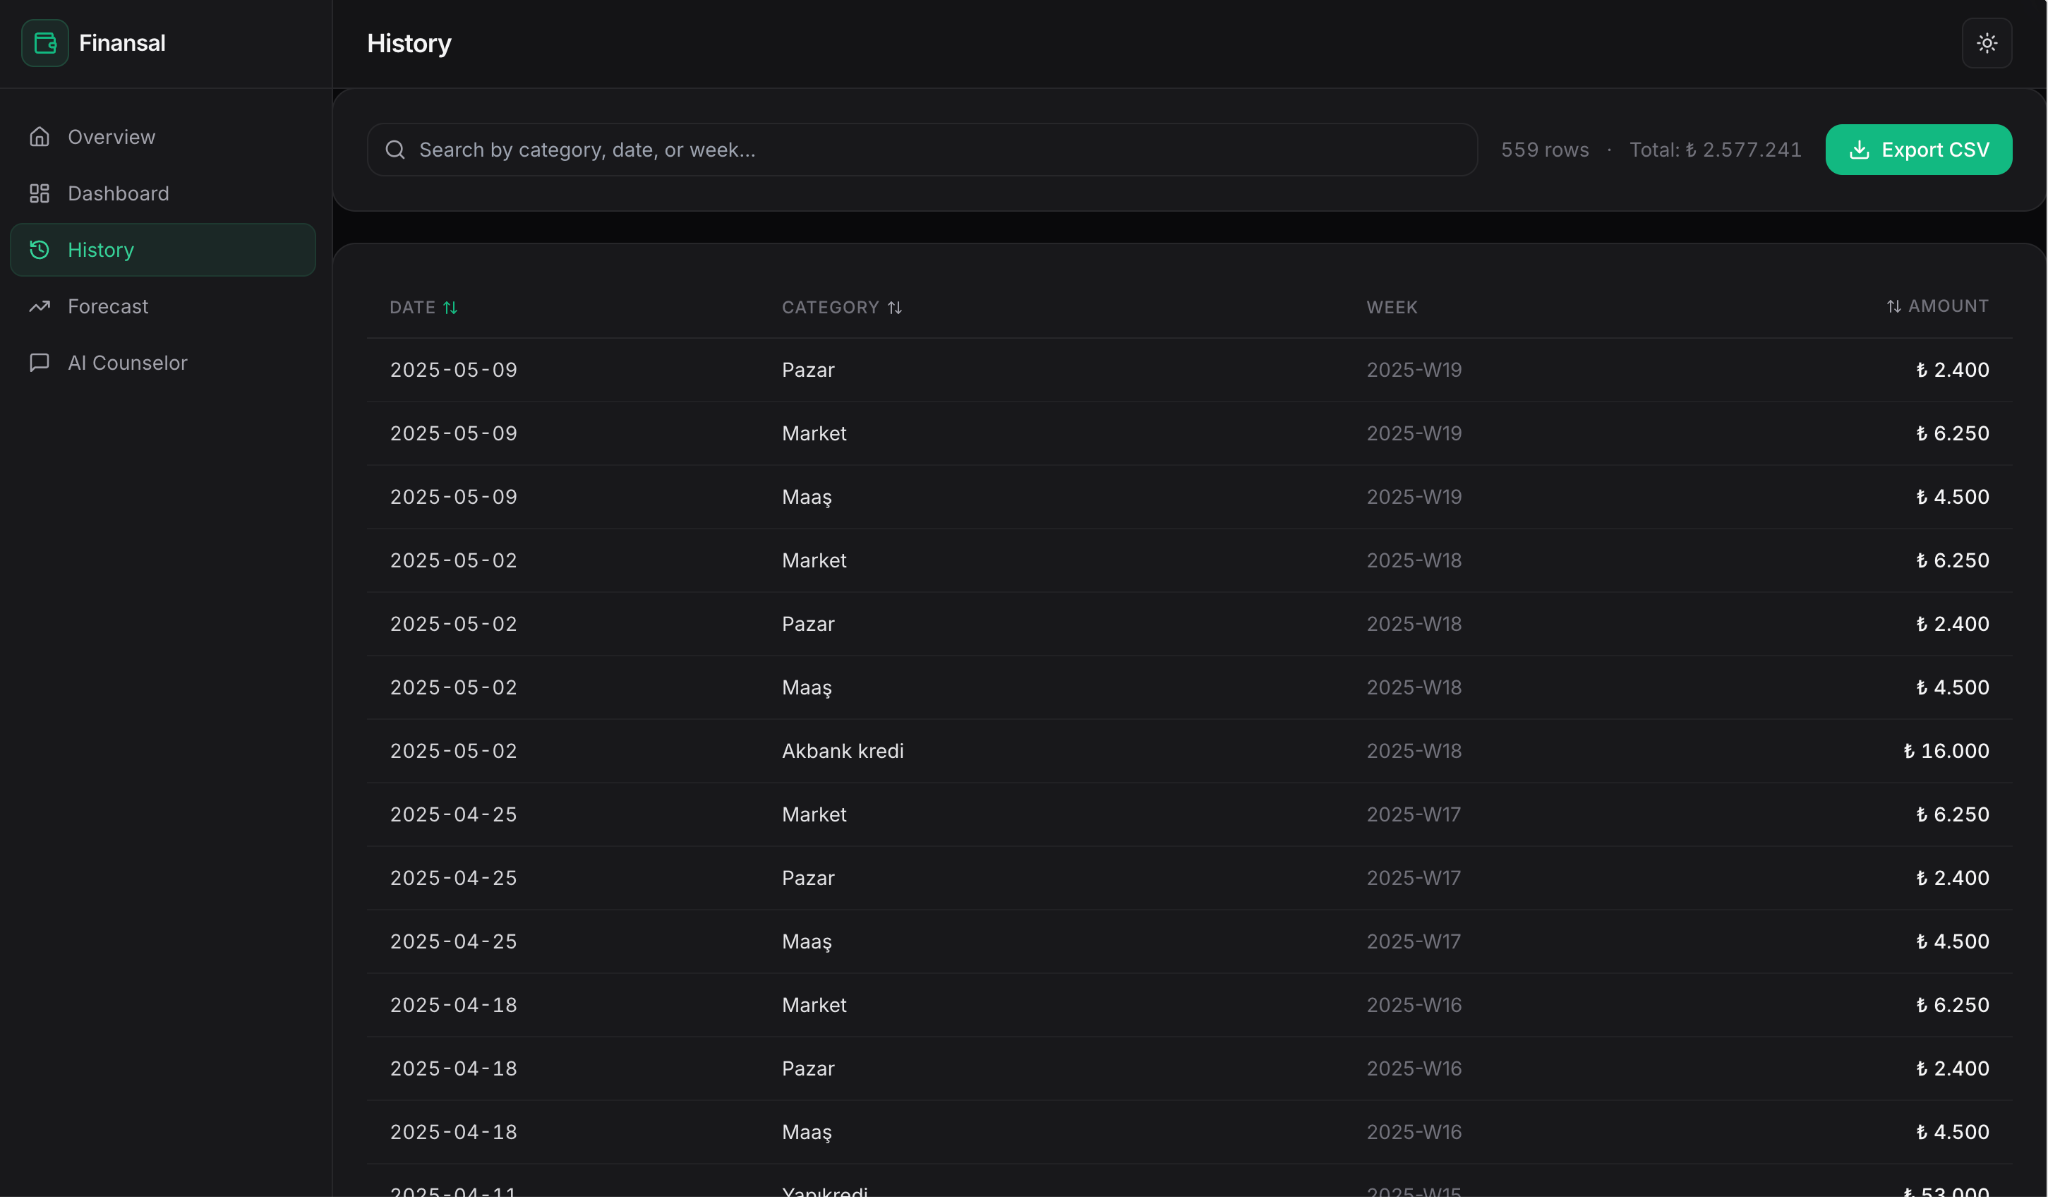
The History tab is the raw log. Every transaction, every row.
You can filter by category, date, or amount. The table is sortable and paginated. This is the page you open when you remember spending something and want to find the line.
Predictions
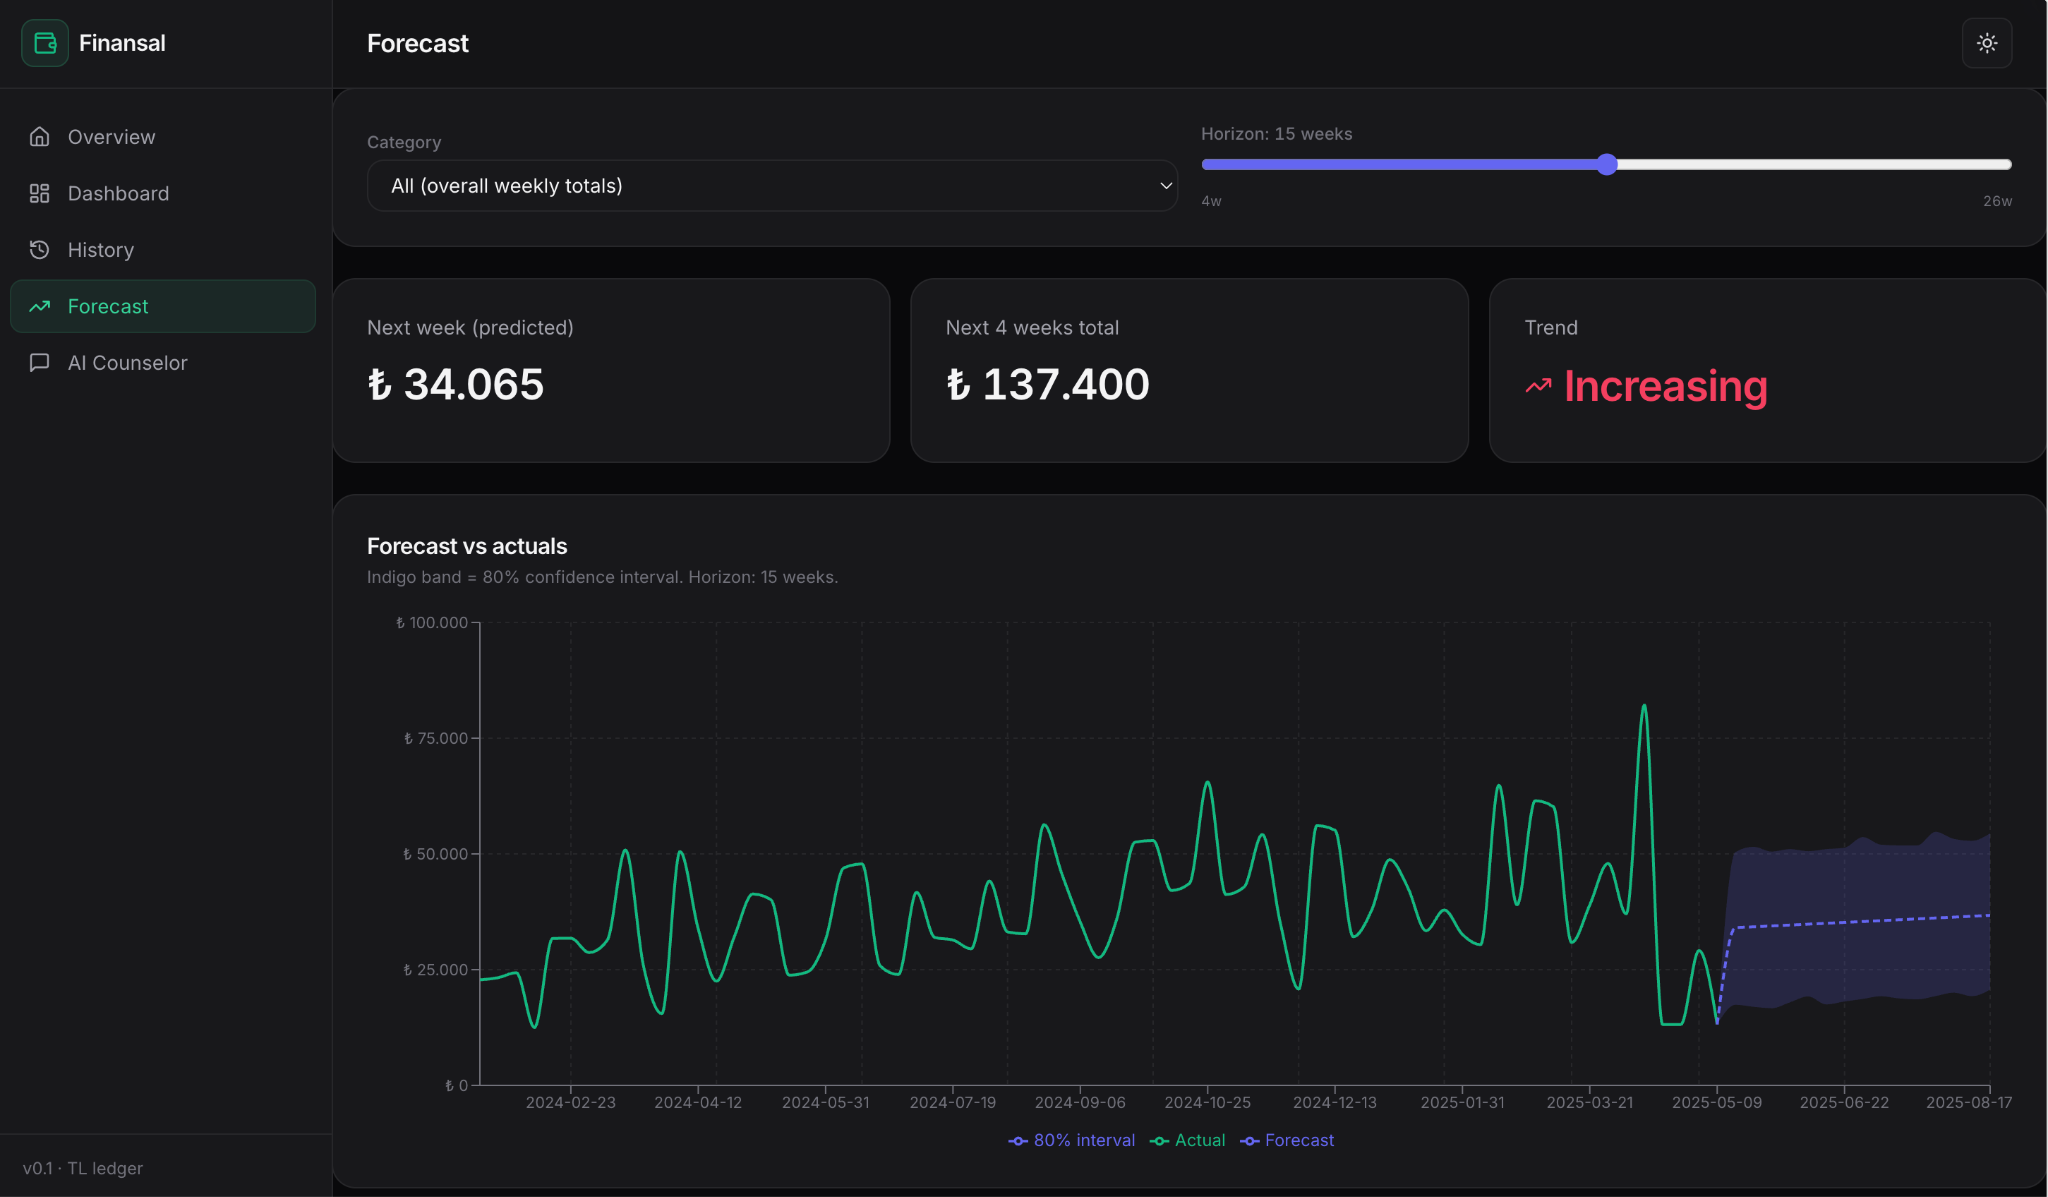
The Forecast page is where the Prophet engine earns its keep.
Pick a forecast window with the slider. The model returns the next period’s total, with confidence intervals plotted underneath. A short summary tells you whether your spending is increasing, decreasing, or holding.
The line chart at the bottom shows the forecast against the actual history, so you can see how the model is reading your pattern.
AI Counselor
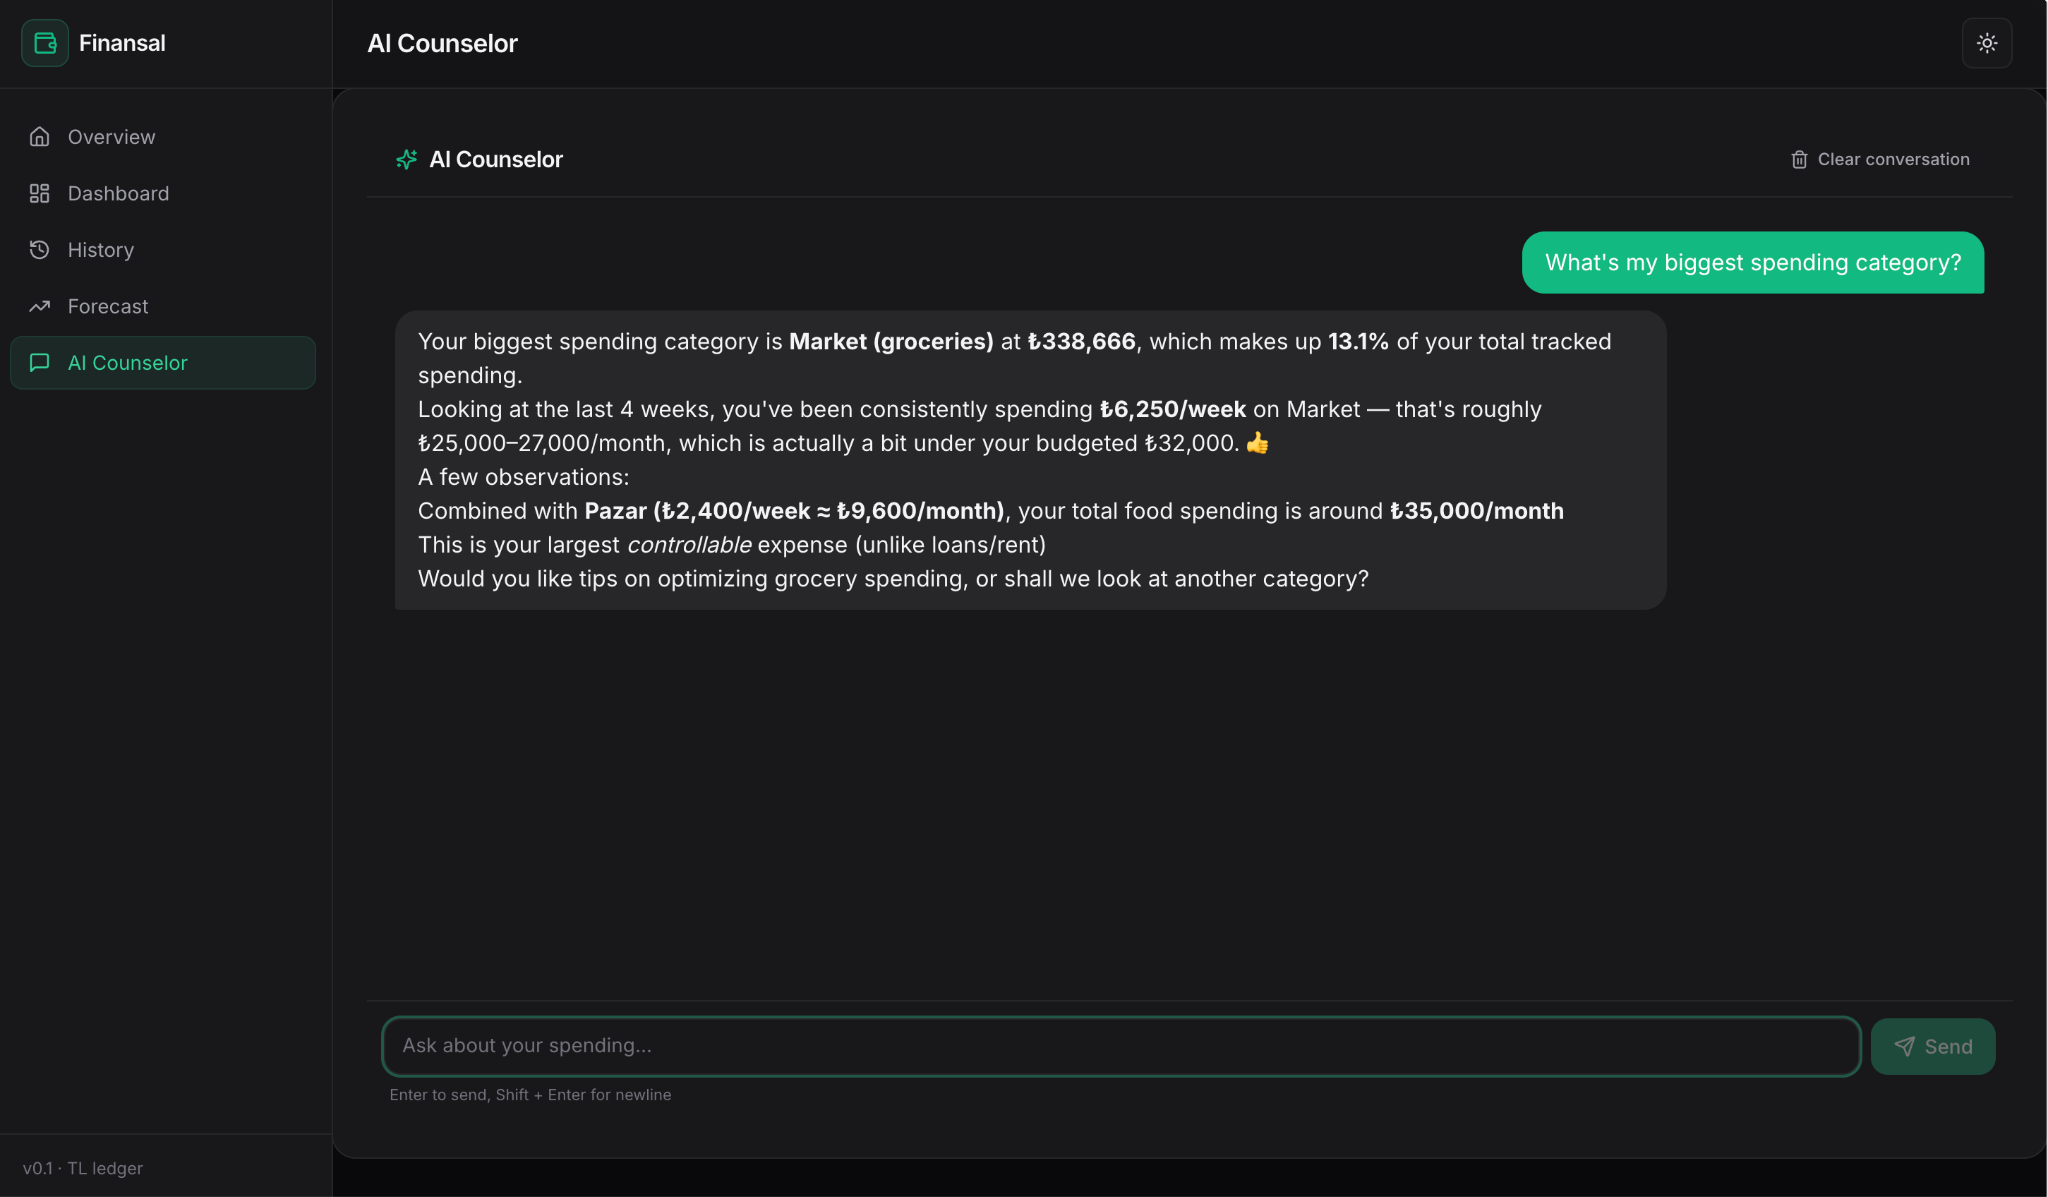
The AI Counselor is a chat interface trained on your data. It has your full expense history loaded as context, so you can ask anything specific.
“Where should I cut back?”
“Compare this month to last month.”
“What’s my biggest expense category?”
“Will I exceed $3,000 this month?”
To make this work, you need to put your API key in.
Use this prompt:
“Save this Claude API Key for AI counselor, here is mine <paste-your-key-here>”
Paste your key in there.
The backend reads from .env automatically when it starts, so you do not have to wire anything up manually.
It can be OpenAI, Claude API, or you can grab a free one from OpenRouter or Ollama.
One last thing. If you plan to push this project to GitHub, make sure your .gitignore file includes .env.
Step 4: Browser Testing with Playwright CLI
Once the dashboard looks right, you can run automated browser tests with Playwright CLI.
If you want to install this, here is the link to it: https://github.com/microsoft/playwright-cli
Use this prompt, so it can install it for you.
“Install Playwright CLI in this project and set up a basic config for testing the React app running on localhost:5173.”
Once installed, use this prompt to run the actual tests:
“Use Playwright CLI to test the app end-to-end:
- Navigate to each of the 5 pages: Overview, Dashboard, History, Forecast, AI Counselor
- Verify charts render on each page
- Submit a chat message to AI Counselor and verify a response comes back
- Screenshot every page and save them to /tests/screenshots
- Report any failures with the relevant trace”
If something breaks, follow up with this:
“Read the Playwright trace from the failed test and dispatch the relevant sub-agent to patch the bug. Re-run the test after.”
That last one closes the loop. Claude reads the trace, sends the fix to whichever sub-agent owns the broken page, and re-tests until it passes.
But if your app doesn’t get errors like mine, you won’t have to. Now let’s check the dashboard.
How Can You Adapt This to Your Use Case?
The expense tracker is an example. The pattern is the point.
Five sub-agents, one orchestrator, one tester. The data changes. The frontend changes. The structure stays.
Some swaps that work right now.
Client dashboard: swap the CSV for your client’s data, swap “expense categories” for “project status,” keep the five pages.
Personal CRM: swap the data layer for a contacts JSON, swap Predictions for “next follow-up suggestion,” keep the AI Counselor as your relationship advisor.
Content tracker: swap the CSV for your post analytics, swap Predictions for “next post topic forecast,” keep everything else.
The sub-agent definitions stay almost identical. You change the prompt’s first paragraph. The five agents handle the rest.
The Bigger Picture
One prompt used to build an app. Now one prompt builds a team.
The shift is from prompter to orchestrator. You stop writing apps. You start running five agents that build, test, and fix without you in the loop.
The data is yours. The agents are yours. The dashboard is yours.

Awesome article, just as usual! Love the building type of articles, always learn something new!
Interesting will test this out.